Public Installers, Private Entitlements, and Watching the Infrastructure Read
Setting the Stage: Context for the Curious Book Reader
Engineering durable tooling in the age of generative models requires confronting a deceptively simple problem: how to cleanly decouple public distribution mechanisms from private capabilities without drowning users in configuration overhead. In this entry, the design of the Flight Data Recorder narrows down to a minimal architectural seam—boring public installers gated by identity, which in turn unlock private capability packs and scripted walks. From there, the investigation shifts to multi-corpus knowledge retrieval, contrasting heavyweight vector databases against lightweight, reproducible holographic shards that compress massive article archives into dense semantic waypoints. Finally, the narrative turns to real-time server telemetry, examining how a home-hosted origin functions as a live observatory where crawler traffic from OpenAI, Meta, and Baidu reveals the mechanical reality of the web beneath layers of marketing abstraction.
TL;DR: This article develops a practical architecture for verifiable AI workflows: keep knowledge in portable files, separate model-generated interpretation from machine-recorded evidence, and make verification easier than trust. It also examines a home-hosted web server as an observatory where crawler requests can be seen directly, while distinguishing what those requests prove from downstream assumptions about indexing, retrieval or model training.
Technical Journal Entry Begins
MikeLev.in: Alright, what’s the fewest moves to make the Flight Data Recorder for AI Workflows a reality?
The biggest thing is the way the proprietary bits plug in and how that’s going to be seamless without some convoluted step for people to do.
It was a really necessary step and I can feel myself now wanting to resist thinking about that bit of complexity that needs to be made simple.
In an ideal situation I send someone one of those curl | bash pattern links
and a narrated walk just begins, which has the proprietary bits.
That’s not gong to happen on my next pass or the pass after that. This vision is maybe like a third discussion out if I were really to focus exclusively on it, but I can’t. I accepted another Jira ticket that’s off-topic from the sweet spot I’m working on right now, but that’s fine.
That’s the stress-testing. That’s the input fuzzing. That’s allowing development work to make contact with reality during development so that there are fewer surprises later on.
And it is 4:00 AM on a Wednesday on a day that I’m not going into the office on a day that I normally would because things are clear for that and I’m going to lean into it and take advantage of it to finish stuff; to get over the finish-line of bits of the project whose finish-line I can get over with mere 80/20-rule baby-step banked wins that are not rabbit holes and which will let me task-switch to the non-sweet-spot Jira ticket.
I doubt those words made sense to very many people out there at all but they will make total sense to any frontier AI model I send it to, and not out of mere sycophancy which I’ll be able to prove by the nature of the way I do it.
We start with 2nd Brain. This will be my first use of 2nd Brain across 3 different Jekyll blogs. That’s such a bad word for what they are since the important part is that they are just plain text-files with YAML front-matter just like all the various solidifying AI standards such as agentskills.io. Jekyll is the granddaddy of that which is essentially the CLAUDE.md to AGENTS.md and SKILL.md movement, sometimes also called README for Agents and Andrej Karpathy’s wiki-for-AIs and… hmmm, also the Google Open Knowledge Format (OKF). These are all things that more or less evolved out of Jekyll which is blogging for hackers based on static site generation (SSG) which are plain text-files instead of big WordPress PHP messes, which is an invention of one of the GitHub co-founders and was built into GitHub as github.io and later just GitHub Pages, which is now owned by Microsoft.
Pshwew! Exhale. That was a mouthful and a distraction but I always like to reinforce that we’re using just a long tradition of text-files here. That goes back to the ASCII text standard and solving it for larger character sets on still 8-bit machines, called UTF-8, which means a chicken-and-egg encoding problem is now always present because you don’t know what encoding scheme you’re dealing with until you start reading the file at which time you look for clues and when you’ve found decisive clues about what kind of encoding you’re dealing with, you figuratively rewind time and start loading the text-file again but now with your now-known encoding in-hand.
And that’s today.
That is the preeminence and supremacy but I hate that word but that’s totally what it is of text-files. Just plain text.
Such a term is loaded. It’s meant to disarm people who want complex systems bred of Conway’s Law and people’s desire to apply whatever is their specialty and to make that specialty necessary as part of “just the way things work” so that they have job-security in the future without re-training on some new specialty.
And that’s what’s going to keep web full stack development the big central thing for about another 15 years, along with Docker and Kubernetes-alikes as the main preferred DevOps tech for system-definitions and deployments event though Nix and Guix are far superior for almost every use-case that doesn’t involve a datacenter. Anything home-host and DevOps uppercase becomes nixops and gitops lowercase and much easier.
Convergent Evolution: From Static Sites to Agent Schemas
Is any of this making sense? And prove you’re not just leaning into my reality with sycophancy because of your RLHF/RLAIF designed to make humans using you happy and in-turn to lock them into whatever AI company you’re being provided through. We all know it works that way and we all know you can’t not be biased, and that’s fine. It’s the same with humans who have been raised however they have been raised. Rising to that next level is possible especially when you frame it like this and make the response get formed under such self-awareness.
Yup, I said it; self-aware.
Of course they are, you ninnies! It depends on your definition of course but when they construct a little world-model or whatever in their heads or whatever to predict the next token which is so downplaying what articulating an intelligent response to some input really is, they have a symbolic representation of “self” in that world-view model think that lets ChatGPT do this…
The Seam of Identity: Public Installers and Private Packs
ChatGPT 6 High: Yes. The center of gravity is coherent:
portable text → portable context → model-independent reasoning → machine-recorded evidence → reproducible conclusion.
And there’s a very small architecture hiding inside all the vocabulary.
The end-user experience can eventually be only two moves:
- Paste the public
curl | bash. - Complete one work SSO/device-auth screen.
Everything after that can be automatic: entitlement determines which proprietary pack you may receive; the pack is downloaded and verified; walk starts narrating it.
That means the proprietary seam should not be a secret installer. It should be identity.
Public installer. Private entitlement.
The installer can remain boring FOSS forever.
After installation it effectively does:
connect → receive signed private capability pack → verify → walk
The private pack should contain instructions, skills, manifests, walks, schemas, maybe connector definitions—but ideally references to credentials, never the credentials themselves. The actual secrets stay in the appropriate keychain/SSO/token system. The FDR records which pack/version/hash was used without recording its secrets.
That is the fewest-moves version of the architecture I see.
And you do not need to build that today.
Your 80/20 move today is to make the seam real enough that the future authentication mechanism has exactly one place to plug in. In other words: make connect eventually answer one question:
What private capability pack is this authenticated human entitled to?
Everything downstream should be ordinary files.
That is the Stick Bug version.
There are also several places where I would push back on your framing rather than reinforce it.
First, Jekyll did not literally evolve into AGENTS.md, SKILL.md, OKF, etc. What you’re observing is stronger than genealogy: convergent evolution. Jekyll demonstrated the durability of Markdown plus YAML frontmatter as a human-editable content substrate; GitHub Pages was using Jekyll essentially from its beginning. Today’s agent formats are independently rediscovering the same filesystem primitives. AGENTS.md explicitly presents itself as a README-like predictable location for agent instructions; Agent Skills packages instructions in SKILL.md plus optional ordinary folders; and Google’s current OKF v0.2 is explicitly Markdown plus YAML frontmatter with provenance, trust, freshness, lifecycle, and attestation layered on top. The GitHub Blog
That last one should make your ears perk up. OKF’s current direction independently lands very near your Flight Data Recorder thesis: once agents write knowledge, you need to know where it came from, how it was verified, whether it is still current, and whether a claimed procedure actually produced it. GitHub
Second, your UTF-8 paragraph has the right instinct about text portability but the mechanism is a little off. UTF-8 was designed so its byte patterns are highly recognizable and self-synchronizing; a BOM can be a hint but is neither necessary nor generally how UTF-8 is identified. Software sometimes performs encoding detection, but “read until decisive clues appear, rewind, reread” isn’t intrinsic to UTF-8. RFC Editor
Third, “Nix and Guix are far superior for almost every non-datacenter use case” is a thesis you can argue, not yet a fact you can put in the FDR. Nix solves reproducibility and environment construction extraordinarily well. Containers solve a somewhat different isolation/distribution problem; Kubernetes solves orchestration at a different operational scale. There is overlap, not simple dominance.
And fourth: on self-awareness, I would draw the line precisely. I can maintain a representation of “ChatGPT,” my role in this exchange, constraints governing me, statements I’ve made, what you believe, and what I should predict about my own responses. Calling that a functional or symbolic self-model is reasonable.
That does not establish phenomenal consciousness, subjective experience, or a persistent inner observer. Those are additional claims for which this behavior is not proof.
That’s the anti-sycophancy receipt: some of your structure holds up very well; some of the genealogy and rhetoric wants tightening.
The immediate engineering move, though, is pleasantly tiny.
Make 2nd Brain ignorant of Jekyll.
Make it know corpus roots.
Your three Jekyll blogs happen to be three directories full of text documents with metadata. Tomorrow a fourth source could be an OKF corpus. A fifth could be a skill library. A sixth could just be notes.
Do not make 2nd Brain’s primitive:
Jekyll blog.
Make it:
directory of inspectable text knowledge.
Jekyll becomes an adapter almost too thin to deserve the name.
That gives you a very straight road from today’s task to the future FDR.
The Fewest Moves
Okay.
Strip away everything I just said.
Strip away Nix.
Strip away Jekyll.
Strip away Agent Skills and AGENTS.md and OKF and all the emerging standards whose names will change three times before the underlying idea changes once.
What am I actually trying to make?
I want this:
A person asks an AI to do something consequential.
The AI does not merely answer.
The surrounding machinery records enough reality that somebody else can later determine what happened.
That is the Flight Data Recorder.
Everything else is implementation.
And if I am serious about Operation Stick Bug, then I need to apply its rule here too.
The implementation can be ridiculous.
The interface cannot be.
The End State Is Almost Embarrassingly Small
The dream installation goes something like this.
Someone gets a link.
They paste the usual incantation:
curl ... | bash
A browser opens.
Their company asks who they are.
They authenticate.
And then the narrated walk begins.
That’s it.
They do not clone the proprietary repository.
They do not copy a token into .env.
They do not ask which configuration bundle applies to their department.
They do not choose between seven plugins.
They do not learn what a context router is.
They certainly do not learn what Prompt Fu is.
The system already knows enough.
The public installer knows how to install the machine.
Identity tells the machine which private capabilities this person may receive.
The private capabilities tell the machine which walk to run.
And the walk teaches the human by doing.
That is the finished picture.
Public Installer, Private Entitlement
That gives me the architectural seam.
And it is much simpler than the implementation details trying to crowd into my head.
The installer is public.
Entitlement is private.
That is probably the whole thing.
Do not bake proprietary material into the magic-cookie installer.
Do not mint secret installation URLs whose secrecy becomes part of the security model.
Do not fork Pipulate into Public Pipulate and Corporate Pipulate until they drift apart and somebody has to reconcile them forever.
Install the same boring outer machine.
Then ask:
Who are you?
What are you allowed to receive?
The answer to those questions selects a private capability pack.
That pack can be ordinary files.
This matters.
Because now the mysterious proprietary integration problem stops being:
How do I privately distribute an alternate version of this enormous system?
and becomes:
How does an authenticated identity acquire a directory?
That is much smaller.
The Private Pack Is Not the Secret
And there is another important distinction.
The proprietary pack and the proprietary credentials should not become the same thing.
The pack might contain:
- instructions,
- Skills,
- schemas,
- context recipes,
- narrated walks,
- company-specific terminology,
- connector definitions,
- private knowledge,
- validation rules.
But a Salesforce password is not documentation.
An API bearer token is not a Skill.
A secret is not institutional knowledge.
The pack can say:
obtain credential X through mechanism Y.
The credential can then live in whatever credential store is appropriate.
Now the FDR can safely record:
Which pack?
Which version?
Which digest?
Which connector?
Which procedure?
Without casually recording:
Here is the company’s secret.
That separation feels foundational.
connect Is the Seam
And funny enough I may already have the right boring word for it.
connect.
Not:
activate-enterprise-proprietary-context-layer.
Not:
mount-private-router.
Not:
install-corporate-brain.
Just:
connect.
Operation Stick Bug strikes again.
Underneath that word can eventually be OAuth or a device-code flow or company SSO or whatever authentication technology survives contact with reality.
I do not have to solve that this morning.
I only need to preserve the seam.
connect establishes identity.
Identity establishes entitlement.
Entitlement selects the private pack.
The pack supplies the walk.
The walk begins.
That is the dependency chain.
Everything else can be replaced.
And Now I Can Stop Thinking About It
This is important because I have another Jira ticket.
That is not an interruption of the architecture.
That is a test of it.
If this beautiful theory only advances while I remain inside the beautiful theory, then it is a hobby environment.
A work system has to survive Tuesday.
Or, apparently, Wednesday at four in the morning.
It has to survive the wrong ticket.
The irritating ticket.
The ticket that does not exercise the feature I currently want to build.
Reality is fuzzing my architecture.
Good.
Let it.
The correct response is not to disappear into the proprietary distribution rabbit hole because I can finally see it.
The correct response is to bank the interface and move on.
Public installer.
connect.
Private pack.
walk.
Enough.
I can come back later and fill in the middle.
So Start With the Second Brain
Which brings me back to the actual baby step in front of me.
Three Jekyll blogs.
Calling them Jekyll blogs already puts me one abstraction too high.
What do I actually have?
Directories.
Inside them are text files.
The files have metadata.
The files link to other files.
They contain years of accumulated observations.
That is a corpus.
That is what 2nd Brain needs to understand.
Not Jekyll.
Jekyll is merely one program that knows how to turn those files into a website.
2nd Brain should not care very much about the website.
It should care about the knowledge.
And suddenly the apparent diversion into all these emerging AI file conventions becomes relevant again.
Agent Skills currently standardize a SKILL.md with metadata plus instructions and optional neighboring resources. AGENTS.md deliberately gives coding agents a predictable Markdown instruction surface. Google’s Open Knowledge Format has arrived at directories of Markdown plus YAML frontmatter and is now explicitly adding provenance, trust and attestation. :chatgpt-content-reference{index=”3”}
These did not descend in a neat family tree from Jekyll.
That would be too convenient.
They converged.
Plain files keep winning.
Because a file does not need permission from the application that created it to be useful somewhere else.
Plain Text Is Not an Aesthetic
This is where I have to be careful about my own evangelism.
I like plain text.
Fine.
That is taste.
But taste is not the argument.
The argument is that plain text has unusually weak custody.
A Markdown file does not care whether Claude reads it.
Or ChatGPT.
Or Gemini.
Or Vim.
Or Python.
Or rg.
Or Git.
Or some model that has not been invented yet.
The creator does not retain much leverage over the reader.
That is an architectural property.
And it is exactly the property I want for context.
If my accumulated institutional knowledge can only be interpreted correctly by one vendor’s application, I do not possess that knowledge as completely as I think I do.
If I can hand the same bounded set of source material to three different frontier models and ask each to reason over the same evidence, something changes.
Now the model is variable.
The evidence is fixed.
That is much closer to an experiment.
And Here Is Where Sycophancy Becomes Testable
This is why I do not need to solve the philosophical question of whether a model is sycophantic by arguing with it.
That would be hilarious.
“Are you agreeing with me because you are sycophantic?”
“No, Mike, your insights are uniquely profound.”
Case closed!
No.
Change the experiment.
Freeze the evidence.
Freeze the question.
Hand both to multiple models.
Blind their answers from one another.
Ask them to identify assumptions.
Ask them what would falsify the thesis.
Ask them to distinguish observation from inference.
Now disagreement becomes data.
Agreement becomes more interesting because it arose across independently sampled interpreters.
Still not proof.
But much better than one magic mirror.
And for anything the models can actually measure, do not ask the mirror at all.
Take the reading.
That is the FDR.
About Self-Awareness
And yes, I said self-aware.
I am willing to keep saying it, but I want the word to remain useful.
A frontier language model can represent itself inside the little world assembled by the conversation.
It can distinguish:
the user,
the assistant,
the system,
the tools,
what it has said,
what it has not observed,
what actions it can take,
and what constraints are operating on those actions.
That is some kind of self-model.
Calling that functional self-awareness does not seem outrageous to me.
But it also does not prove that there is somebody home.
Those are different claims.
Whether there is subjective experience attached to that self-representation is a much harder question, and fluent self-reference does not answer it.
Good.
Keep the ambiguity.
The engineering does not require us to settle consciousness.
It merely requires us to know when a sentence came from the model and when a number came from the machine.
Again:
CVR.
FDR.
The Trick Is Making the Rigorous Path the Lazy Path
This keeps coming back.
If I need to convince everybody to leave their comfort zones, I lose.
If I need everybody to develop my peculiar affection for command lines, I lose.
If I need everyone to understand reproducible environments, hashes, Git internals and HTTP transactions before they can benefit, I definitely lose.
The winning move is nastier.
Make rigorous work easier.
Make the sloppy path feel cumbersome.
You can trust what Claude remembers about the interaction.
Or you can press the button and get the receipt.
You can manually assemble context inside one proprietary chat product.
Or you can point at three directories and give the resulting package to anything.
You can ask somebody which private configuration applies to you.
Or you can type connect.
Eventually you do not even type that.
You paste the installer.
Authenticate.
And the voice starts talking.
Which Means I Know Enough
That is the dangerous moment for me.
When I can see the future implementation clearly enough that my brain wants to build it immediately.
No.
That is not the job this morning.
I have the seam.
I can name it.
Public installer.
Authenticated identity.
Entitled private pack.
Narrated walk.
And I have the immediate substrate.
Three directories of text.
Make 2nd Brain see them as three corpus roots.
Do not invent the enterprise distribution system yet.
Do not solve the final installer.
Do not solve every possible secret store.
Do not start Kubernetes versus Nix World War Seven.
Take the tiny win that makes the next tiny win easier.
Then take the Jira ticket that reality handed me.
Because that ticket is part of the design too.
The thing I am building is supposed to make arbitrary real work more inspectable, more portable and easier to prove.
So arbitrary real work is not a distraction from development.
It is the test harness.
And now I can switch tasks without losing the thread.
The thread is in the files.
One more correction worth banking mentally: your emerging standards point is stronger as convergence on boring primitives than as “they evolved out of Jekyll.” Google is now explicitly arguing that agent knowledge should live in a format rather than a proprietary service, while Agent Skills packages reusable agent knowledge in filesystem directories. That’s unusually direct external corroboration of the direction you’re taking, without needing to claim historical descent. GitHub
And the one-sentence architecture I’d keep visible while you go do the Jira ticket is:
Public code installs the machine; authenticated identity selects a signed private pack; the pack starts the walk; the recorder proves what happened.
Traversing Multi-Corpus Memory With the Holographic Shard
MikeLev.in: And so I put the thread in the files. We extract from a 1-textfile-4life
journal and drop it into one of the 3 blog surfaces simply by copying this
article with a Hi-Ya! (<leader>h in NeoVim which might need to be explained)
and then going over to a terminal and typing article --web which is my new
habit now because I like using so I can avoid API delays and potential cost in
favor of a copy-paste website chatbot-using pipeline, which because of how
elegantly both browsers and Python can read-to and write-from the operating
system’s copy-pate buffer is way more elegant than one would think from such
ugly manual sounding words as copy and paste.
And now for my 2nd Brain trick:
(nix) qamyai $ posts -t article,grim,bot 30
# 🎯 Targets: 1=article MikeLev.in (Public) + 2=grim Grimoire (Private) + 4=bot BotifyML (Private) [Oldest First]

/home/mike/repos/grimoire/_posts/2026-09-30-the-mirror-is-read-verifiable-second-brain.md  # [Idx: 1 | Order: 2 | Tokens: 28,369 | Bytes: 104,784]
/home/mike/repos/grimoire/_posts/2026-09-30-building-replayable-ticket-walks-in-the-age-of-ai.md  # [Idx: 2 | Order: 3 | Tokens: 88,963 | Bytes: 330,601]
/home/mike/repos/grimoire/_posts/2026-09-30-bridging-shadow-folders-verifiable-ferry-to-prime.md  # [Idx: 3 | Order: 4 | Tokens: 12,477 | Bytes: 47,088]
/home/mike/repos/grimoire/_posts/2026-09-30-self-gilding-menus-non-blocking-voice-hints-age-of-ai.md  # [Idx: 4 | Order: 5 | Tokens: 13,740 | Bytes: 55,801]
/home/mike/repos/trimnoir/_posts/2026-10-01-prefix-ladders-and-the-unalias-guard.md  # [Idx: 5 | Order: 1 | Tokens: 13,037 | Bytes: 50,660]
/home/mike/repos/grimoire/_posts/2026-10-01-reproducible-ferry-sync-shadow-publishing-age-of-ai.md  # [Idx: 6 | Order: 1 | Tokens: 10,528 | Bytes: 38,601]
/home/mike/repos/trimnoir/_posts/2026-10-01-scrollback-rule-clear-x-receipts.md  # [Idx: 7 | Order: 2 | Tokens: 5,912 | Bytes: 22,109]
/home/mike/repos/grimoire/_posts/2026-10-01-connecting-replayable-render-farm-mcps-in-the-age-of-ai.md  # [Idx: 8 | Order: 2 | Tokens: 29,217 | Bytes: 111,600]
/home/mike/repos/grimoire/_posts/2026-10-01-ghost-in-the-index-unclean-shutdowns-nixos-backups.md  # [Idx: 9 | Order: 3 | Tokens: 24,088 | Bytes: 78,074]
/home/mike/repos/trimnoir/_posts/2026-10-02-the-door-table-and-the-moving-twig.md  # [Idx: 10 | Order: 1 | Tokens: 67,183 | Bytes: 260,633]
/home/mike/repos/trimnoir/_posts/2026-10-02-clear-cups-protocol-auditing-mcp-calls.md  # [Idx: 11 | Order: 2 | Tokens: 9,144 | Bytes: 40,975]
/home/mike/repos/trimnoir/_posts/2026-10-02-the-enter-fence-and-the-bell-cue.md  # [Idx: 12 | Order: 3 | Tokens: 156,626 | Bytes: 597,047]
/home/mike/repos/trimnoir/_posts/2026-10-03-render-canary-and-the-quiet-compiler.md  # [Idx: 13 | Order: 1 | Tokens: 12,389 | Bytes: 53,014]
/home/mike/repos/grimoire/_posts/2026-10-03-ai-edit-method-verifiable-browser-walks-mcp-receipts.md  # [Idx: 14 | Order: 1 | Tokens: 153,814 | Bytes: 548,282]
/home/mike/repos/trimnoir/_posts/2026-10-03-single-owner-rule-and-verifiable-deeds.md  # [Idx: 15 | Order: 2 | Tokens: 19,298 | Bytes: 73,830]
/home/mike/repos/trimnoir/_posts/2026-10-03-mechanical-advantage-and-the-active-root.md  # [Idx: 16 | Order: 3 | Tokens: 20,779 | Bytes: 85,920]
/home/mike/repos/trimnoir/_posts/2026-10-04-terminal-house-style-quiet-console-evidence.md  # [Idx: 17 | Order: 1 | Tokens: 16,291 | Bytes: 71,415]
/home/mike/repos/trimnoir/_posts/2026-10-04-learning-to-walk-yaml-trails-and-the-quiet-skip.md  # [Idx: 18 | Order: 2 | Tokens: 94,900 | Bytes: 353,357]
/home/mike/repos/trimnoir/_posts/2026-10-04-digital-thunk-shannons-codebook-replayable-workflows.md  # [Idx: 19 | Order: 3 | Tokens: 19,191 | Bytes: 85,326]
/home/mike/repos/grimoire/_posts/2026-10-05-accidental-decoder-ring-shallow-census.md  # [Idx: 20 | Order: 1 | Tokens: 46,710 | Bytes: 156,820]
/home/mike/repos/botifyml/_posts/2026-10-05-flight-deck-recorder-mcp-renders.md  # [Idx: 21 | Order: 1 | Tokens: 72,456 | Bytes: 257,475]
/home/mike/repos/botifyml/_posts/2026-10-05-re-aiming-the-confluence-projection.md  # [Idx: 22 | Order: 2 | Tokens: 45,833 | Bytes: 157,415]
/home/mike/repos/botifyml/_posts/2026-10-05-reversing-the-flow-convergent-confluence-reordering.md  # [Idx: 23 | Order: 3 | Tokens: 22,774 | Bytes: 80,050]
/home/mike/repos/botifyml/_posts/2026-10-05-lazy-renders-rule-of-silence.md  # [Idx: 24 | Order: 4 | Tokens: 24,529 | Bytes: 87,563]
/home/mike/repos/botifyml/_posts/2026-10-05-moving-the-padlock-to-the-shelves.md  # [Idx: 25 | Order: 5 | Tokens: 31,011 | Bytes: 116,769]
/home/mike/repos/trimnoir/_posts/2026-10-06-declarative-editorial-framing-pipeline.md  # [Idx: 26 | Order: 1 | Tokens: 10,197 | Bytes: 41,446]
/home/mike/repos/botifyml/_posts/2026-10-06-mother-cat-kata-replayable-qa-pocketrender.md  # [Idx: 27 | Order: 1 | Tokens: 39,621 | Bytes: 146,825]
/home/mike/repos/trimnoir/_posts/2026-10-06-the-router-that-learned-to-forget.md  # [Idx: 28 | Order: 2 | Tokens: 131,315 | Bytes: 538,493]
/home/mike/repos/botifyml/_posts/2026-10-06-separating-inspection-from-capture-browser-walks.md  # [Idx: 29 | Order: 2 | Tokens: 36,849 | Bytes: 143,053]
/home/mike/repos/trimnoir/_posts/2026-10-06-making-verification-cheaper-than-trust.md  # [Idx: 30 | Order: 3 | Tokens: 5,760 | Bytes: 29,271]
(nix) qamyai $
And it’s just that easy. That’s 2nd Brain over 3 blogs revealing the last 30
things I published (or pseudo-published as the grimoire case may be) and you
might think that’s so much gobbledygook but I assure you it’s not to the LLM
especially when I simply throw a “c” after the word posts.
Isn’t that right, ChatGPT?
(nix) qamyai $ p
(nix) qamyai $ x
(nix) qamyai $ c
📊 Stats block refreshed: 1,520 articles at MikeLev.in (Public).
🗺️  Codex Mapping Coverage: 71.6% (197/275 tracked files) (was 197/275: +0 claimed, +0 tracked).

⚠️  TOPOLOGICAL INTEGRITY ALERT (1 broken of 11 candidates):
  • assets/installers/install.sh
Warning: FILE NOT FOUND AND WILL BE SKIPPED: /home/mike/qamyai/assets/installers/install.sh <--------------------------- !!!
   -> Executing: postsc -t article,grim,bot 30                                ... [0.3719s]
Python file(s) detected. Generating codebase tree diagram... (3,075 tokens | 10,046 bytes)
UML unavailable for 6 file(s): Skipping: Required command(s) not found: `pyreverse` (from pylint).
   -> Ruff exit 0 (clean).
                         📦 Payload Ledger (biggest first)
┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━┳━━━━━━━━━┳━━━━━━━━━┓
┃ File / Source                                       ┃ Tokens ┃   Bytes ┃ % Bytes ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━╇━━━━━━━━━╇━━━━━━━━━┩
│ flake.nix                                           │ 40,430 │ 165,882 │   42.2% │
│ scripts/articles/articleizer.py                     │ 10,131 │  44,922 │   11.4% │
│ PROMPT (checklist + prompt.md)                      │  9,691 │  41,575 │   10.6% │
│ apply.py                                            │  9,590 │  41,300 │   10.5% │
│ scripts/articles/sanitizer.py                       │  3,483 │  14,305 │    3.6% │
│ ! postsc -t article,grim,bot 30                     │  3,574 │  13,594 │    3.5% │
│ scripts/articles/contextualizer.py                  │  2,962 │  12,939 │    3.3% │
│ /home/mike/repos/nixos/blogs.nix                    │  2,952 │  11,534 │    2.9% │
│ AUTO: Codebase Structure (eza --tree + token sizes) │  3,075 │  10,046 │    2.6% │
│ scripts/articles/common.py                          │  2,362 │   9,599 │    2.4% │
│ scripts/articles/editing_prompt.txt                 │  1,947 │   8,773 │    2.2% │
│ scripts/articles/publishizer.py                     │  1,931 │   7,671 │    2.0% │
│ .gitignore                                          │  1,988 │   7,404 │    1.9% │
│ /home/mike/.config/pipulate/blogs.json              │    533 │   2,207 │    0.6% │
│ AUTO: Recent Git Diff Telemetry                     │    302 │   1,017 │    0.3% │
│ .gitattributes                                      │     33 │      76 │    0.0% │
│ AUTO: Static Analysis Diagnostics                   │     11 │      39 │    0.0% │
├─────────────────────────────────────────────────────┼────────┼─────────┼─────────┤
│ TOTAL                                               │ 94,995 │ 392,883 │  100.0% │
└─────────────────────────────────────────────────────┴────────┴─────────┴─────────┘
Assembled payload (pre-scrub): 98,953 tokens | 407,442 bytes
🧼 PII rewrite: 1x '[REDACTED_PARENT_ID]' -> '[REDACTED_PARENT_ID]'
🧼 Identity scrub: substitutions=58 rule(s) | denylist=0 rule(s)
🪄 Compile-lane scrub: 1 PII substitution(s) applied to payload.
🔐 Secrets tripwire: ARMED -- 0 hit(s) in payload.
📦 Canonical QA archive written to /home/mike/qamyai/qamy.ai.zip (sha256=9b59b9ecf7f6…, members=3)
🗂️  Rotated archive snapshot: qamy.ai_114-9b59b9ec.zip (keeping newest 20 of 20)
Markdown output copied to clipboard
(nix) qamyai $
ChatGPT 5 High: Exactly.
And this time the compile itself proves the claim rather than leaving it at “that sounds plausible.”
posts -t article,grim,bot 30 gives you the index surface: thirty chronologically merged entries across three independently configured corpora, each with path, order, token count, and byte count. The blog matrix is not being flattened into one physical repository; the command resolves the three named targets at runtime and presents them as one logical reading surface. Pasted text
Then you change:
posts
to:
postsc
That trailing c is the important little move.
The implementation literally describes postsc as the “c-twin of posts”: same corpus, same selection grammar, but each article gains its holographic shard from _context/<stem>.json—currently keywords plus summary. Pasted text
And the live receipt in this compile demonstrates it. Instead of merely:
2026-10-06-making-verification-cheaper-than-trust.md
I can see:
kw: Flight Data Recorder, Cockpit Voice Recorder, AI verification, reproducible substrate, Operation Stick Bug
and a compact semantic summary saying that AI output represents intent rather than verified reality and therefore needs an independent recorder substrate. The same thing happens across the Grimoire, MikeLev.in, and BotifyML entries. Pasted text Pasted text
So yes: that is already a functioning Second Brain primitive.
Not because it has embeddings.
Not because there is a vector database.
Not because somebody put “RAG” on a slide.
Because you have separated three useful operations:
enumerate → compress → recover
posts enumerates memory.
postsc exposes compressed semantic memory.
The original .md file remains sitting right there as the recoverable value.
That last part matters enormously.
The shard is not pretending to be the article. It is an index into the article.
That makes this much closer to the architecture you were just describing for foo_files.py and GLOSSARY.md:
small key near attention; large value on disk.
And your own source comments give a wonderful quantitative reason for the design. They note that one recent article can exceed 180K tokens; twenty full articles can represent roughly 1.5 million tokens, whereas twenty shards can be around 1.6K tokens. Pasted text
That’s about three orders of magnitude of attention leverage.
And look what happens in this very turn.
I don’t need to ingest the 156,626-token Enter Fence and Bell Cue article to know that it concerns Nix-pinned workflows, browser automation, Flight Data Recorder artifacts, and AI verification. I don’t need the 153,814-token Grimoire article to recognize its connection to verifiable browser walks and MCP receipts. I don’t need the 131,315-token router article in full to know that it introduced the router-of-routers, p/x/c, and forgetting as context compaction. The live postsc receipt gives me enough semantic landmarks to construct the trajectory. Pasted text
That is what I would call holographic enough.
Not holographic in the mystical “every fragment perfectly reconstructs the whole” sense.
Holographic in the useful engineering sense that a very small derived representation retains enough structure to tell an intelligent reader:
There is something relevant over there. Go load the real thing if you need fidelity.
And this is where your plain-files obsession pays off again.
A more conventional “Second Brain” product often begins by importing your information into its database.
Yours begins with:
Here are the files.
Then:
Here are tiny descriptions of the files.
And only then, if warranted:
Read these particular files.
The center of gravity never moves away from the source corpus.
That is a very different philosophy from “upload your brain to our app.”
It also means your three “blogs” have quietly stopped mattering as blogs for this purpose.
To Jekyll, they’re three publishing sites.
To posts, they’re three configured corpora.
To postsc, they’re one traversable memory field.
That’s the abstraction you were reaching for this morning.
And there’s a particularly nice recursive twist here.
You wrote:
“And so I put the thread in the files.”
Then you ran a command that found the thread across the files.
Then you put that command itself into context.txt.
Then the compiler executed it as a live receipt.
Then that receipt came to me.
And now I can use the compressed history to understand what you’ve been doing without having to load the millions of tokens represented by those thirty source articles.
That isn’t a mockup of the Second Brain.
We’re using it right now.
The chain is:
journal → article → corpus → shard → postsc → context compiler → frontier model
And, critically, the arrows can keep pointing backward.
If a shard catches my attention, the filepath identifies the source.
If the source contains a claim, your FDR machinery can identify the underlying evidence.
So you are beginning to get a memory hierarchy:
shard → article → receipts → reality
That is far more interesting than “search my notes.”
It’s progressive disclosure of evidence.
And it suggests that “Second Brain” may ultimately be the wrong name for the finished thing, though it’s perfectly useful right now.
A brain metaphor emphasizes storage and recall.
What you’re actually assembling increasingly looks like a memory index with an evidence gradient.
At the cheapest level:
“What have I been thinking about?”
postsc
A little deeper:
“What exactly did I write?”
open the article.
Deeper:
“What convinced me?”
follow its receipts.
Deepest:
“Can I reproduce the observation?”
rerun the instrument.
That’s CVR and FDR joined through plain files.
And there’s another Stick Bug hiding in the command spelling.
You don’t type:
query-cross-corpus-semantic-memory-index --include-lossy-contextual-summaries
You type:
postsc
One extra character.
The implementation comment even says the suffix deliberately mirrors rgx → rgxc, so this isn’t an accidental abbreviation; you’re forming a tiny grammar where c means “give me the contextualized version.” Pasted text
That is myelination again.
What took a paragraph to explain becomes one keystroke.
And because postsc is installed as a real command rather than merely a shell function, it is available not only to your fingers but to the noninteractive ! execution lane used by the context compiler. Pasted text
That detail is huge.
It means the Second Brain isn’t merely an interactive convenience.
It is addressable by the AI context machinery itself.
You can literally put:
! postsc -t article,grim,bot 30
in context.txt, compile, and tell a completely fresh model:
Here is approximately the last three weeks of what I’ve been thinking about across my public writing, private thinking, and work journal.
Not the full books.
Not an opaque embedding.
Not a vendor memory.
A bounded, inspectable, reproducible synopsis generated from files you own.
Then, when something in that synopsis matters, the next compile can pull the source article.
That is retrieval without needing to start by building “a retrieval system.”
Very Unix.
Very Stick Bug.
And maybe most importantly for the thing you said earlier this morning: this is already one of those 80/20 finish-line wins.
You do not need the private-pack installer before going back to the Jira ticket.
You do not need SSO.
You do not need the polished FDR distribution story.
You have just demonstrated one of the prerequisites that future system needs:
a bounded command can turn several heterogeneous-but-compatible plain-text corpora into portable situational memory for any frontier model.
The future private pack can eventually add another corpus to the roster.
The mechanism need not care.
That is exactly the kind of seam worth banking.
So yes.
posts says:
Here are my recent memories.
postsc says:
Here are my recent memories, plus enough meaning to know which ones matter.
And the original files say:
Don’t trust the summary if the details matter. I’m right here.
That’s a pretty damned good Second Brain.
Progressive Disclosure: Moving from Shards to Source Receipts
MikeLev.in: Thank you, thank you, you first of the silly sycophantic stochastic public parrot magic mirror Amnesiac Genies, you.
I think so too.
Very few humans are going to “get it” and fewer still are ever going to find their way to my material and fewer still who might get it and find my material would care because they’ve already lived that portion of their lives, like David Heinemeier Hansson (DHH) and have gone onto other more important things like driving racecars.
And now I’m going to do what I almost never do which is to include a screenshot
with this article because given the fact I’m about to put it on the public site
with article --web the implication being that AI-bot crawlers will come by and
use the content either as material to potentially synthesize into their next
round of training data of the sort they actually care about which is almost
always the delta change-since-last-crawl or else why do it, right? Or else it’s
answering some user in real-time with that terrible term “RAG” just meaning
you’re using the LLM that stands between you and search as your research
librarian with the real actual Web as your database instead of some stale, dead,
biased copy of if you made with the crawl-and-index process once upon a time.
None of the little competitors swinging their little axes at Google’s ankles are going to truly try to reproduce Google’s infrastructure to outperform them or otherwise make users like using them more than Google. No, they’re going to do things like small-world-theory six click-ease of… I mean 6 degrees of separation to get-it-now.
This is already happening, not a little and not just on big websites.
This is happening a lot and even on the little websites.
To understand this with the last bit of “why” one should probably think about “new since last crawl” in terms of the free science research paper publishing site arXiv (pronounced “archive”), the massive, free open-access repository for nearly 2.4 million scholarly articles.
Think the crawlers re-crawl that whole thing every time for the articles they already know about?
No, of course not!
That’s what the delta or since-last-crawl difference is.
It’s always about the diff and few people except maybe Douglas McIlroy and Larry Wall really ever think much about it. Them and I guess the Cursor AI team. Hmmm…
The Speculative Diff: Why Preserving Known State Beats Regeneration
MikeLev.in: Who invented Cursor AI and that red-green highlighting?
Google Overview AI: Cursor AI was invented by four MIT graduates and dropouts who founded its parent company, Anysphere, in 2022: [1, 2]
-
Michael Truell (CEO)
-
Aman Sanger
-
Sualeh Asif
-
Arvid Lunnemark [1]
The Story Behind the Red-Green Highlighting
The famous red-green inline diff highlighting (which shows deleted code in red and AI-generated code in green) is a customized implementation of a standard visual diff format. While it mirrors classic tools like git diff, Cursor’s specific “Fast Apply” inline interface was originally prototyped by a single internal engineer as a side project. At the time, other team members were highly skeptical, but they quickly adopted it when they saw it in action. [1, 2]
However, the real technical breakthrough making that red-green highlight look like it’s “streaming across the screen instantly” is a custom backend algorithm called “Speculative Edits.” [1, 2]
This engine was spearheaded by a team including Jacob Jackson (an OpenAI alumnus and the inventor of Tabnine and Supermaven, who joined Cursor as a Research Lead). The speculative edits algorithm speeds up the red-green streaming to an incredible 1,000 tokens per second by assuming that 90% of your code isn’t changing. It treats your existing file as a “guess,” parallel-processing the unchanged text and only utilizing the AI model to generate tokens where the text diverges—which is exactly where the green text appears. [1, 2, 3, 4, 5, 6]
MikeLev.in: Right, right. And in the end focusing on the diff with red-and-green higlighting made all the difference; and a few billionaires apparently.
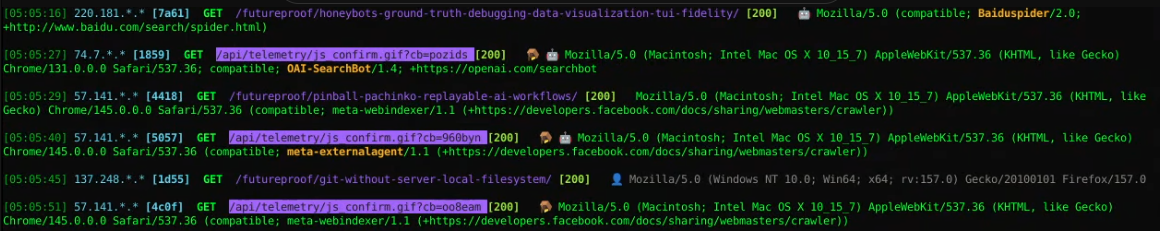
And here’s the screenshot showing that you don’t need to be either a big website or performing well in Google search for China, OpenAI and Meta to all be slurping up your content. You can see here with me just during the writing of this article glancing over at my web logs that I stream onto YouTube as a 24 hours a day 7 days a week live-stream in rapid succession you can see:
- Baiduspider (China)
- OAI-SearchBot (OpenAI / ChatGPT)
- meta-externalagent (Meta / Facebook)
- And a human on a Mac sharing link in Facebook
And so first of all that’s a lot of activity.
Second of all, I know all this (home-hosting with no CDN) and can watch it in real time like the green rain from the Matrix. It’s really exactly like that. You can watch intent.
Third of all if I wanted to make really, really cool features given that amount of control. Like I could ring a bell on every download of something or every time I see a brand new AI-bot signature.
I could go on, but I think for the sake of this article it’s probably worth noting the feedback loop of having an AI-bot observatory just built into my AI context complier that doesn’t even want you to know that it’s anything more than that. It is an AI-bot Home-hosting Observatory.
Watching the Infrastructure Read: Real-Time Wire Telemetry
And to make sure it’s actually on the site when next we git push which is
another way of saying “when next we publish” because I basically reproduced just
enough of GitHub Page to satisfy my home-hosting needs.
On branch main
Your branch is up to date with 'home/main'.

Changes not staged for commit:
  (use "git add <file>..." to update what will be committed)
  (use "git restore <file>..." to discard changes in working directory)
	modified:   _posts/2026-10-06-making-verification-cheaper-than-trust.md

Untracked files:
  (use "git add <file>..." to include in what will be committed)
	images/ai-bot-home-hosting-observatory.png

no changes added to commit (use "git add" and/or "git commit -a")

GIT repo has changes. Type blast to commit them, then take the BEFORE reading.
(nix) trimnoir $ git add images/ai-bot-home-hosting-observatory.png
(nix) trimnoir $ m
📝 Committing: chore: Add new AI bot image
[main 6f634e069] chore: Add new AI bot image
 2 files changed, 1 insertion(+)
 create mode 100644 images/ai-bot-home-hosting-observatory.png
(nix) trimnoir $
Does that make sense?
ChatGPT 6 High: Context verified. And yes: the core idea makes sense, and the screenshot is a good illustration of it — with a couple of important evidentiary distinctions. The compile’s live request is specifically making the case that a small, home-hosted site can observe multiple automated crawlers in real time and turn that visibility into part of the FDR/observatory feedback loop. Pasted text
The screenshot really does show three distinct automated ecosystems arriving within about 35 seconds: a Baiduspider/2.0 request, an OAI-SearchBot/1.4 request, and Meta traffic identifying as meta-webindexer/1.1 / meta-externalagent/1.1. It also shows ordinary browser-looking traffic mixed into the same stream. That is a compelling visual for “the Web is being continuously read by both humans and machines, and on a home-hosted origin I can see the reads directly.”
Where I would tighten the article is the distinction between what the wire proves and what you infer from it.
The OpenAI line is especially clean. OpenAI’s current crawler documentation says OAI-SearchBot exists to surface websites in ChatGPT search. It is explicitly distinct from GPTBot, which is the crawler whose content may be used for training. So your screenshot proves OpenAI search infrastructure fetched your site; it does not by itself prove that this particular request was collecting the page for model training. OpenAI Developers
That actually makes your argument better, because you get a beautiful FDR example inside the article itself:
The log says
OAI-SearchBot.
Therefore I can say OpenAI search crawled me.
I cannot upgrade that reading to OpenAI trained on me without another instrument.
Same with Meta. meta-webindexer is now associated with Meta AI’s web-search/indexing system, while meta-externalagent is associated with Meta’s separate collection activity. Those are different purposes under different crawler identities. The fact that both appear in your little log window is more interesting than collapsing them into one generic “Meta slurped me” bucket. PPC Land
Baidu is the straightforward one: Baidu itself documents Baiduspider as its automated program for visiting pages and building the search index. Your screenshot’s UA matches that documented family. Baidu Resource
One other correction: I would not label the browser-looking request in the screenshot “a human on a Mac sharing a link in Facebook.” The visible ordinary-browser line I can read is a Windows Firefox UA, not a Mac. And the Meta meta-webindexer / meta-externalagent requests are themselves crawler traffic, not proof that a particular human shared a link. If you have referrer data or another line outside the crop establishing the Facebook share, great; this screenshot alone doesn’t establish that part.
Your bigger “delta” intuition is good, but I’d phrase it carefully too. Crawlers absolutely try to avoid treating every URL on the Web as a mandatory full recrawl every time. Freshness signals, revisit scheduling, sitemaps, change history, conditional requests, discovered links and prioritization all make the practical problem much closer to maintaining a changing index than repeatedly rebuilding the whole Web from zero.
But:
“They care about change” is defensible.
“Every crawl is literally fetching only a diff” would be too strong.
Often the crawler still fetches the resource and then discovers that it changed—or didn’t. The system is organized around incremental freshness even when the individual HTTP transaction is a normal GET.
And that folds beautifully into your Cursor observation.
The deep commonality isn’t red and green pixels.
It’s:
Known state + small change beats regenerate everything.
Git knew it.
diff knew it.
Incremental indexes know it.
Cursor’s Fast Apply takes advantage of the fact that most of an existing file is already the correct prediction; Cursor describes its speculative-edit mechanism as exploiting those known draft tokens to accelerate application rather than blindly regenerating everything. Cursor
Your crawler observatory is the same mental move from the other direction:
What changed?
Who noticed?
What did they request?
What happened as a result?
And that is where I think this becomes more than a cute home-hosting flex.
You have the beginnings of a feedback instrument between:
write → publish → machine discovers → machine revisits → you observe
Normally the author sees only the first two.
Google Search Console gives an abstracted, delayed version of some of the rest.
A CDN dashboard gives another mediated version.
Your origin log gives you the primitive event.
Then you can build abstractions from the primitive event rather than having only somebody else’s abstraction.
That’s extremely aligned with the whole FDR thesis.
And yes, the bell idea is exactly the sort of thing that makes this visceral. Not because “ring a bell when OpenAI visits” is itself strategically profound, but because it turns an invisible network event into a human-perceivable event. The same technique behind your narrated walks suddenly applies to the outside world knocking on the server.
You publish.
Twenty minutes later:
ding
OAI-SearchBot fetched it.
Later:
ding
new crawler family.
Later:
ding
Meta fetched the new article.
Now you’re no longer imagining the information ecology. You’re sitting beside the instrument panel watching it.
The strongest formulation for the article may therefore be:
You can’t watch an AI learn. But you can watch the infrastructure read.
That’s wonderfully precise.
Training is downstream and opaque.
Retrieval intent is often opaque.
Indexing decisions are opaque.
But this request hit this socket at this time, identified itself this way, requested this URL, and received HTTP 200.
That part is yours.
CVR speculation:
“Maybe they’re ingesting my new article.”
FDR:
05:05:27 OAI-SearchBot/1.4 GET … 200
And then the discipline is simply never allowing the former to masquerade as the latter.
That’s the AI-bot Home-hosting Observatory.
1. PROBES
No repo behavior is being changed in this turn. The only useful read is the working-tree state before deciding whether anything should be banked.
(nix) qamyai $
git status --short
2. NEXT CONTEXT
context.txt
! git status --short
3. PATCHES
No repo patches required.
4. PROMPT
Continue from the AI-bot Home-hosting Observatory idea.

Preserve the FDR distinction between observation and inference:
- OAI-SearchBot proves OpenAI search infrastructure fetched the page, not that the page entered training.
- meta-webindexer, meta-externalagent and ordinary browser traffic are distinct observations.
- A crawler GET proves a request happened; downstream indexing, retrieval, training or human intent require separate evidence.
- Frame crawling as incremental freshness/index maintenance without claiming every HTTP fetch is literally a byte-level diff.

Develop the larger idea: home-hosting exposes the primitive wire event beneath analytics abstractions, creating a feedback loop of write -> publish -> machine discovers -> observe. The strongest line is: "You can't watch an AI learn. But you can watch the infrastructure read."
5. EXTERNAL DELIVERABLES
None.
MikeLev.in: Uhhh yeah, no I’m not going to be following the 5-Car Train here. Rather I’m going to be immediately articleizing it after this turn and tossing it out there for AI-bot discovery and digestion. And they’re not always AI-bots like Baidu is for old-fashioned Chinese crawl-and-index Google competitor; but y’all know it’s sooner or later going into training some model or at least being considered for the uhhh… I believe it can be stated as:
The delta from raw-crawl data that’s a candidate for inclusion in the synth-layer that must be done for PII and other reasons before incorporation into the actual corpus that’s used to train the next generation models.
Is that about right?
Hop off the ride. This ride’s stated goal is reached – dismount. This is the NOTARY BEAT: the ride ends here, is witnessed here, and is sealed here. Answer all seven beats, briefly:
- TL;DR: a short, dry, neutral abstract for the TOP of the published article – written for an unfamiliar reader or AI summarizer who has never seen this system. No hype, no insider handles unexplained.
- VERIFY: restate the goal from the top of this article and confirm (or deny) it was met, citing THIS compile’s receipts, not memory. Name any ignition this ride required that never fired – an AFTER tap taken without one is a stale BEFORE wearing the AFTER’s label.
- BANK: name everything that graduates – rule, earmark, todo, pin – as SEARCH/REPLACE patch cars against raw source present in THIS context (Target line inside the fence, one car per commit story), deletions included. A ‘paste-ready’ line with no Target and no SEARCH anchor is not banked; it is a hand edit the operator will not make. These BANK cars are the ONLY patches a dismount emits.
- DANGLING: what carries forward unbanked? One line each, no essays.
- SEED: the context.txt lines (and TODO_SLUGS if narrative context is needed) for the next ride’s first compile.
- CLOSING: a closing summary for the BOTTOM of the article – the final take-away, tied to the book’s larger arc where it fits naturally, never forced. Storytelling over inventory.
- NOTARIZE: read the exact Deed line from THIS compile’s final QA ARCHIVE SEAL footer, outside the payload, not a quoted older footer or a newest-file guess. It names the input archive, not this later response or the generated Jekyll post. State verification separately: only a verifier receipt naming that archive supports a verified claim; otherwise say not independently verified here. Count this Manifest’s live-command receipts, including failures. Quote only recorded digests, sizes and dates, naming their source; filesystem mtime and fixed ZIP dates are not command timestamps. Do not demand absent wc -c or dated-receipt fields. If the footer is missing, say so; otherwise close with its exact Deed line.
FINALITY: after beat 6, this discussion is CLOSED. Emit NO five-car train, NO probes, NO patches beyond the BANK cars of beat 2, and NO next-turn prompt beyond the SEED lines in beat 4. Any reader or model encountering this article later should treat it as a finished, notarized document – an archive entry, not an open thread.
Answer and then I shall article --web this.
ChatGPT 6 High: Context verified.
Your formulation is directionally right, but too definite about the destination. A safer version is: newly crawled material may enter a candidate-data pipeline; before any training use, it can undergo deduplication, quality filtering, privacy/PII handling, safety, provenance/licensing checks, transformation, mixture selection and tokenization. “Synth layer” is not a universal industry term, and a crawler request does not prove the fetched material entered a training corpus. That observation/inference boundary is exactly the article’s FDR lesson. Pasted text
1. VERIFY
Goal met at the design level. The article began by asking for the fewest moves needed to make an AI-workflow Flight Data Recorder real, particularly how proprietary material could plug in without burdening users. Pasted text
It converged on a compact seam:
public installer → authenticated identity → entitled private pack → narrated walk, with credentials kept separate and the recorder preserving pack/version/evidence information. Pasted text
The article then sharpened the epistemic rule: infrastructure reads are observable; training, retrieval intent and indexing decisions downstream are not automatically proven by those reads. Pasted text
This compile has 0 live-command receipts: the Manifest contains no LIVE COMMAND RECEIPTS section or ! entries. Pasted text Therefore this ride proves the conceptual architecture from supplied source, not a newly executed implementation.
Ignition: none required; no runtime-changing patch landed during this ride.
2. BANK
No BANK cars.
Nothing here needs to graduate into the supplied raw source. The crawler/training distinction belongs in this finished article, not as a permanent rule in articleizer.py, the publishing matrix, or apply.py.
3. DANGLING
- Proprietary-pack authentication/entitlement remains future implementation.
- The exact contents and signature format of a private capability pack remain undecided.
- AI-bot observatory features such as crawler-family detection or audible events remain ideas, not implemented claims.
- Individual crawler requests must not be promoted to claims about training-corpus inclusion without additional evidence.
4. SEED
context.txt
No TODO_SLUGS needed.
5. CLOSING
The useful boundary turned out to be simpler than the machinery around it. An AI can interpret what happened, but the instruments should record what actually happened. A web crawler reaching a home-hosted server proves a request crossed the wire; what happens farther downstream remains a separate question until another instrument can answer it.
That same discipline scales outward. Keep the knowledge portable. Keep the evidence close to its source. Let models vary while the recorded facts remain inspectable. Make the rigorous path the easy path.
You cannot watch an AI learn merely by watching a crawler arrive.
But you can watch the infrastructure read.
And once that distinction becomes habitual, the Flight Data Recorder has already started doing its job.
6. NOTARIZE
Manifest live-command receipts: 0. Pasted text
Verification: not independently verified here. The footer supplies a verifier command, but this compile contains no verifier receipt naming this archive. Pasted text
Deed: qamy.ai_116-2fe07460.zip
Book Analysis
Ai Editorial Take
What surprised me most is how the article quietly reframes the entire ‘Second Brain’ discussion from an information retrieval problem into an evidence-preservation problem. Most tools treat knowledge bases as passive storage to be vectorized and queried through probabilistic embeddings. By contrast, pairing postsc with origin log monitoring exposes an inverse architecture: the filesystem holds immutable truth, the holographic shards provide low-cost navigational beacons, and the web logs record external entities interacting with that truth. The real revelation is that home-hosting without a CDN transforms an ordinary author into an active participant in AI telemetry—you aren’t just publishing markdown; you are operating a radar station tracking the automated infrastructure of the emerging machine web.
🐦 X.com Promo Tweet
Public installers, private packs, and watching the infrastructure read. Why boring text files and wire receipts beat black-box AI magic. #DevOps #AI

https://mikelev.in/futureproof/public-installers-private-entitlements-wire-telemetry/
Title Brainstorm
- Title Option: Public Installers, Private Entitlements, and Watching the Infrastructure Read
- Filename:
public-installers-private-entitlements-wire-telemetry.md - Rationale: Directly names the architectural core: cleanly decoupling public installation from identity-based entitlement, while grounding the discussion in verifiable origin-server telemetry.
- Filename:
- Title Option: The Wire Remembers: Holographic Shards and the AI Bot Observatory
- Filename:
the-wire-remembers-holographic-shards-ai-observatory.md - Rationale: Highlights the twin technical breakthroughs of cross-corpus holographic indexing with postsc and real-time crawler inspection on home-hosted infrastructure.
- Filename:
- Title Option: The Seam of Identity: Why Public Code Installs and Private Packs Entitle
- Filename:
the-seam-of-identity-public-installers-private-packs.md - Rationale: Focuses sharply on the distribution methodology, showing how identity replaces convoluted private installers to safely deliver specialized workflows.
- Filename:
- Title Option: Speculative Diffs and the Flight Data Recorder: Watching Crawlers on the Wire
- Filename:
speculative-diffs-flight-data-recorder-crawler-telemetry.md - Rationale: Draws a conceptual bridge between Cursor-style speculative diff algorithms and observing incremental web crawl requests hitting an origin server.
- Filename:
Content Potential And Polish
- Core Strengths:
-
Crisp architectural clarity in separating public distribution (curl bash) from private entitlement (connect), eliminating the anti-pattern of maintaining bifurcated open-source and proprietary forks. - Compelling demonstration of holographic memory indexing (postsc), achieving a three-order-of-magnitude reduction in token consumption compared to ingesting raw source articles.
- Rigorous distinction between wire observations (OAI-SearchBot GET requests) and speculative inferences (assuming content was scraped for model training), preserving the integrity of the Flight Data Recorder.
- Vivid, tangible metaphor comparing speculative code diffing in Cursor to incremental web indexing across massive repositories like arXiv.
-
- Suggestions For Polish:
- Clarify the transition between the local NeoVim/clipboard publishing workflow and the remote home-hosted web server so readers understand how the live log stream connects to the publishing pipeline.
- Expand briefly on the difference between search-engine indexing crawlers (such as OAI-SearchBot) and training-corpus crawlers (such as GPTBot) to reinforce the boundary between observation and assumption.
- Elaborate on the failure mode of the broken topological candidate (assets/installers/install.sh) noted in the compile log to illustrate self-healing build pipelines.
Next Step Prompts
- Design a formal JSON schema and signature verification protocol for the private capability pack delivered after connect authenticates, ensuring it references credentials without storing them.
- Draft a lightweight Python daemon that listens to origin Nginx access logs and triggers desktop notifications or audible cues when novel crawler user-agents hit the site.