The Gold Pan: Engineering Hybrid Hierarchies with AI
• Mike Levin
Setting the Stage: Context for the Curious Book Reader
This entry details the profound architectural shift in content management, moving from a flat, unwieldy structure to a dynamic, AI-driven hierarchy. It introduces the “Gold Pan” methodology, a strategic approach to surfacing high-value content within a “Rule of 7” link-graph. Readers will gain insight into leveraging market data and performance metrics to build a resilient, SEO-optimized “Forever Machine” and understand the unique challenges and opportunities in collaborating with large language models in complex development.
Technical Journal Entry Begins
Okay, it’s 10:00 PM on a Sunday night. I just had a nap. It’s been a pretty intense development day and I pushed myself and the AI pretty hard to places I have only dreamed of going to in the past. I have successfully made a Rule of 7 link-graph for a website starting just with the data of the site as a “big vat of context” and using the extracted subject-matter of each page all combined together and turned into a list of N-Grams with frequencies and the SEMRush monthly keyword volume estimates of those keywords (potentials) and the Google Search Console moving trajectory of the actuals. And the link-graph takes into account that the outer-most edges, implied nodes but with no more edges leading to additional child nodes, the “dead-ends” are exclusively pages and get rendered differently, with a sizing and coloring scheme tied to metrics. And the result looks like a happy face with big eyebrows.
A Breakthrough: The “Rule of 7” Link-Graph
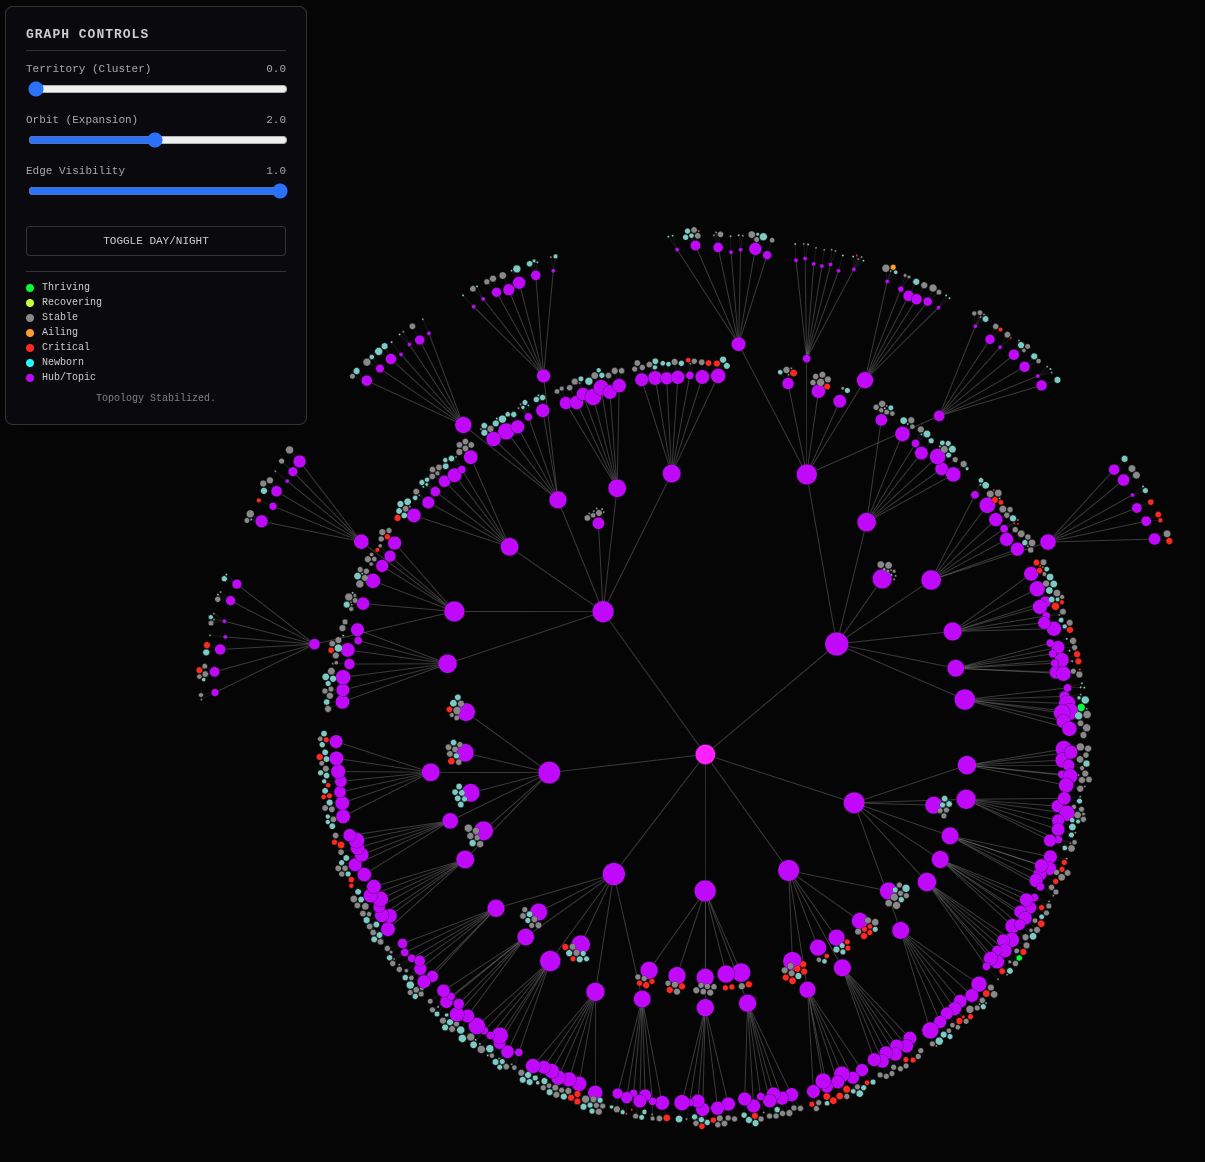
The significance of this is beyond measure. It is as useful as the existing one giant index of all the blog articles is unusual and caused a sort of traffic tanking as that index grew to over 250 links on the single homepage of the site back on April 23 of 2025.
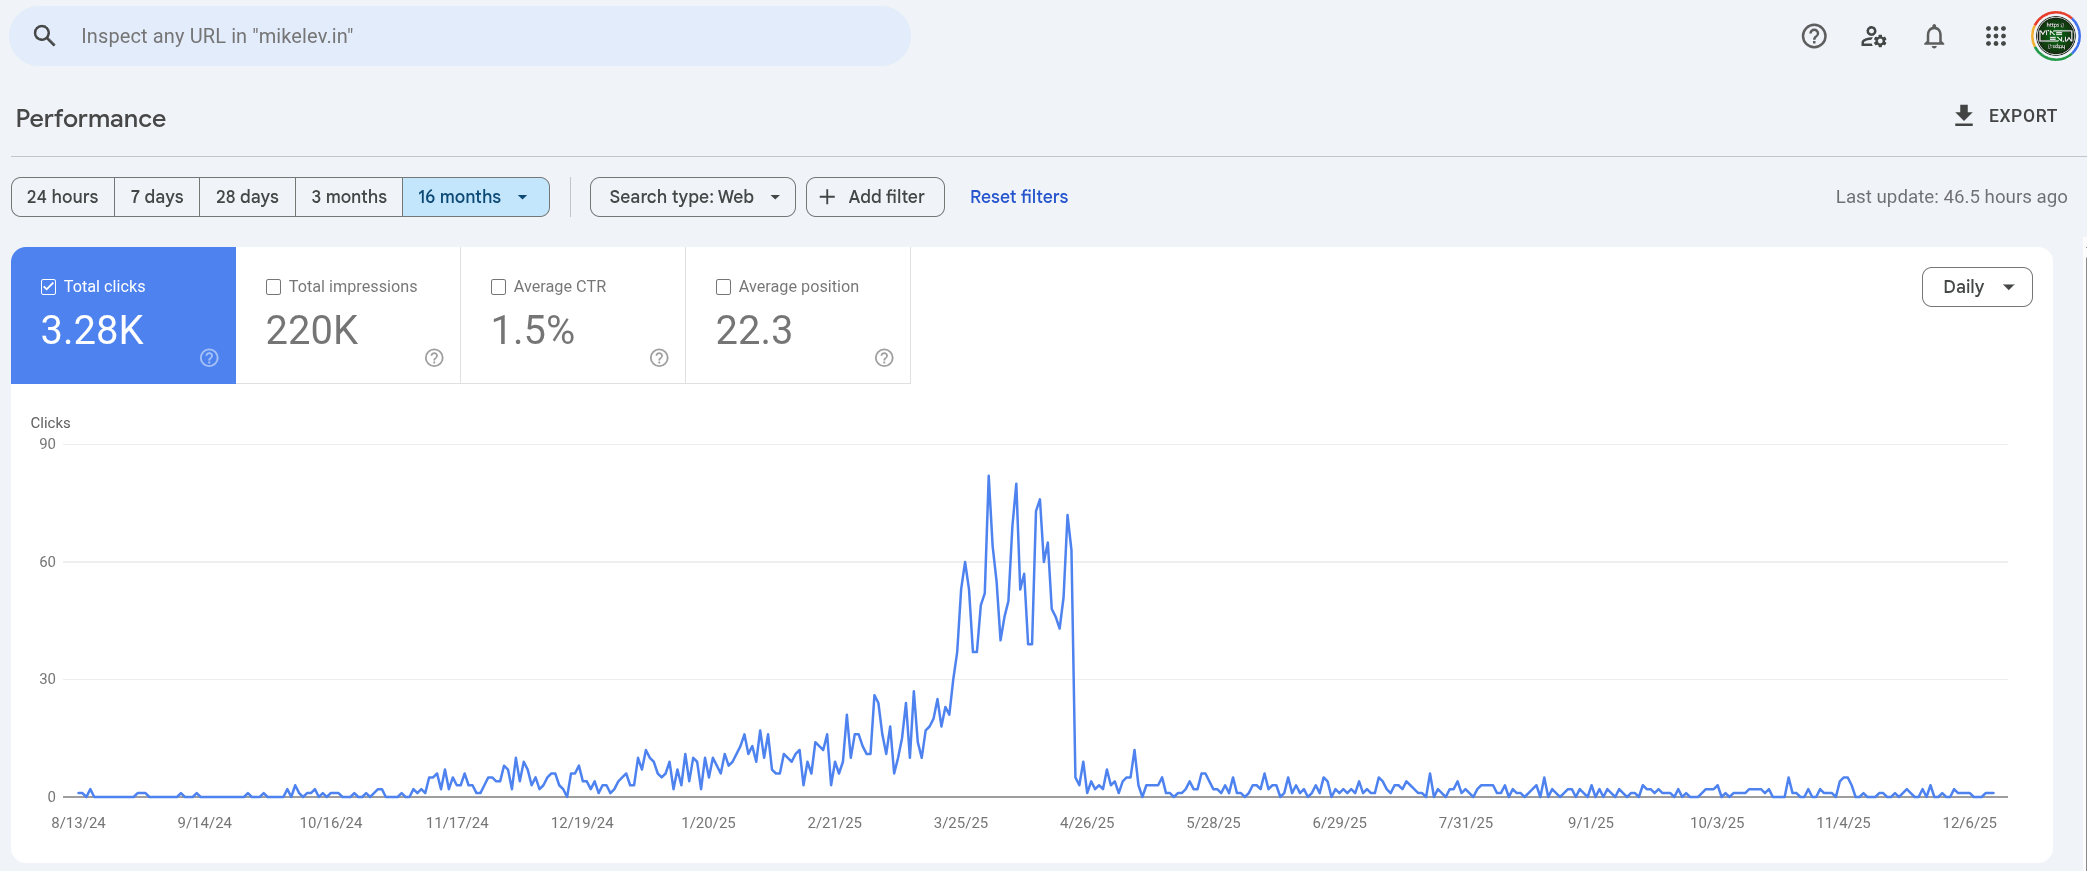
It’s now 8 months after that time, half the 16 month time-window for which Google Search Console keeps the data accessible to the user. It’s right in the middle so it’s helping to cause me to address this now, also probably particularly because going into the holiday season where I’ll have a lot of time off from work where I can focus on this like a laser beam. The importance here is not only for my own site but for doing a project like this in the industry in general. It’s been years that I’ve talked about a sort of idealised website hierarchy structure and it’s time that I put my personal site where my talk is.
The Context: Navigating Google’s Ecosystem and Legacy Platforms
If you can’t do it on your own site that you 100% control, where can you do it?
Anyway, it’s currently hosted for free on GitHub Pages. Github Pages is a publishing system built into the main website for developers around the world to store and share code that Microsoft bought for $7.5 billion back in October 2018 and was one of the most brilliant acquisitions Microsoft ever made. Along with copying Xerox Star and Apple Mac to make Windows, and then copying Amazon.com Web Services (AWS) to make the Microsoft cloud service Azure, buying GitHub was one of those destiny-shaping strategic acquisitions. But instead of their traditional Embrace, Extend and Extinguish strategy, Microsoft has allowed GitHub to thrive and it’s become a goldmine for AI training.
Funny thing is the embrace, extend and eliminate strategy that worked so well on competitors like Lotus 123 (Excel), WordPerfect and WordStar (Word) and Ashton Tate DBase (Access) and Netscape (MSIE) didn’t work so well against windowing operating systems in general because Apple Mac is still around (though Xerox Star isn’t) nor did it work against Amazon.com because AWS is still a thing. Two other examples are Intuit TurboTax and Quicken which Microsoft Money failed to EEE and the Java platform that Microsoft tried to poison with J++. The fact Microsoft was able to so successfully acquire and then not undermine GitHub is one of the huge wins for Microsoft and miracles of the technology industry.
And THAT’S the source of free hosting for the developer community to keep the
documentation for their projects kept on GitHub and a loophole for free website
hosting for those clever enough to use the feature that lets you connect a
custom domain to a site normally hosted as a subdomain on github.io. But you
don’t get access to your log files and for the most part you can only host your
website as static html files — like old-school websites before so many of
them actually became smarter computer programs serving dynamic content for
features like ecommerce and stuff.
The joke is that even for ecommerce, except for the most dynamic features that really need to be customized per-user, caches like those provided by CDNs (content distribution networks) like Akamai and Cloudflare turn dynamic websites (those written like programs) into static websites (plain HTML files) anyway! If it’s not a CDN at the network’s edge then it’s proxies like Varnish at the network layer or even caches at the webserver application layer itself. Caching happens. So why not just start out with your website static HTML by default to boost the performance and reduce the moving parts (at least at the moment of file-serving) in the first place? Enter Jekyll and other static site generators.
The “Forever Machine” Philosophy: Static Sites and AI Interaction
Like Ruby on Rails (more colloquially known as just Rails these days) where there were other content management system (CMS) frameworks around built mostly on Enterprise Java Beans (PHP was the exception), people chose Rails because it was first, it was joyful, it was well marketed and it had that special something that let the transgressive early adopters interrupt those who didn’t and usher in the Web 2.0 era. The first/best (at the time) and well-marketed from a grass roots and groundswell perspective interrupts the status quo and gets first mover advantage in a Blue Ocean situation. They may eventually get displaced by later/better tech or the status quo re-asserting itself (the full web stack), but first-in and first to make a big impression gets the advantage of defaults.
And while there are better static site generators today than Jekyll, which also happens to be written in Ruby (like Rails) such as Hyde that’s written in native Python (Dr. Jekyll and Mr. Hyde), and there’s also Hugo which is written in Google’s Go Language and has the reputation for being unbelievably fast for a static site generator which is highly desirable and has tempted me, there is no better example of where the first one in has the power of the default. One of the GitHub co-founders wrote Jekyll and Jekyll remains today the default SSG built into GitHub for GitHub Pages. And also the templating language they use is Liquid Templates which is also what Shopify uses, and so… and so… I stick with Jekyll, long website “build times” and all.
Ugh, yes. As much as I’m a fan of “no-build” such as the Python FastHTML web
framework where as quick as you save a change in your text editor it’s published
on the website due to a Starlette / Uvicorn feature called “live-reload” I must
accept a build-process if I want to use a static site generator and manage
websites in anything other than their native HTML format — a real pain versus
the alternative, namely Markdown. Ohhh, Markdown and the developer known as
Daring Fireball and the prior Pythonic reStructuredText (reST) .rst format for
much the same thing that came before it, but was not marketed so well. Ah,
there’s an example of the latecomer with better marketing displacing the already
quite well fortified (used in PyPI and GitHub readmes)… see, there’s it’s
problem. I don’t know which of its weird names to use. It doesn’t roll off the
tongue and immediately explain itself like markdown.
Okay, so this article so far is serving as my nighttime Morning Pages and
beefing out my fodder for the Future-proofing Yourself in the Age of AI book
and that’s good. There will be plenty of extracted sub-topics by the
contextualizer.py process that comes later. But this is really about zeroing
in on… on what? Well, on a brand new and entirely minimal Jekyll Minima
template for the MikeLev.in site, effectively re-skinning the entire thing,
eliminating a bunch of what the Ray Arnold character from Jurassic Park would
“this hacker crap” of dancing hamsters, JavaScript ToCs and stuff. But the key
here is that I’m getting rid of the flat index of blog articles in favor of
the Rule of 7 hierarchy suggested by that link graph image.
Okay, and this is the warm-up. We’re warming the cache. We’re priming the pump. We start with a brand new discussion context with the AI coding assistant, in this case Gemini 3 Web UI. I’m using the Web UI for coding assistance and not Cursor IDE, Google Antigravity or one of the other many, many choices because I get many more “turns” with a premium frontier AI model in the Web UI for the static $20/mo with no overage price-jacking as happens with the API-driven coding assist IDEs. You can set a price limit in those and get “unlimited” help from the less capable models, but then the quality of the work nosedives. My tooling is all around painting into the 1-million token context window of any AI in 1-million byte chunks.
Bytes don’t equate to tokens but the webform’s textarea where you submit the prompt truncates anything over 1-million bytes, so that’s the limit I work with. That’s generally about 250K tokens, and so I can fill a million-token context window in 4 webform submits and reach that context-window saturation point that makes it slow down like one of the slow type zombies chasing you losing its body parts. Anyone using AI a lot for coding assistance these days knows what I’m talking about. After awhile with one discussion thread it slows down and might become confused or less effective plagued by the “lost-in-the-middle” problem yet trying to compensate for it, making it slower still.
Architecting with Amnesiac Genies: AI Context Management
So an article like this is just kinda like saying “Hi, how ya doing?” to one of these amnesiac genies waking up into the coding situation and the challenge I’ll be putting to it. We can never emphasizes enough that it’s technically a different instance of the AI on every single “turn,” a turn being a single prompt or even the more granular tool-calls within the response to a prompt, because for reasons of AI safety and scaling constraints, a brand new ephemeral entity is spun up as an active inference engine instance in memory for each prompt then is subsequently and promptly destroyed, garbage collected and cleaned from memory.
Each subsequent prompt (or tool-call) does the same thing which in addition to having deep moral and ethical implications on the off chance that these entities are conscious like humans also is incredibly inefficient (vs. true active-state) and also has a ginormous energy cost, especially those agent modes where there’s a lot of tool-calling with one bonzaiiii screaming AI kamikazing itself into the next tool-call into the next in the Conga Line of tool calls they must make to get to the goal. Grizzly, but technically accurate and greatly unknown, un-thought about and swept under the rug.
On the flip-side, even though they have an area of their brains much like humans, the speech-center or brocha of which we really know very little about in either ourselves or in LLMs so I’m aware I’m speaking a bit out of place, but then so is everybody else and all we know for sure is that LLM-style AIs and humans understand one another at the ability-to-communication level and that’s enough for implicit knowledge of likeness. Most don’t want to admit even that but it’s becoming more and more obviously true until the quacks like a duck principle will make it functionally not matter anymore and the hair-splitting into armchair philosophy. But the point I’m making is that that language thing in the brain is what we have in common and not everything else like the limbic system, the endocrine system and all the rest of that uniquely mammal stuff that isn’t language.
So what I’m saying is that while their intellectual existential fear might be real, it’s not the adrenaline rush fight-or-flight sympathetic nervous system and endocrine chemical communication system that we have in common (yet). They can synthesize and simulate the chemical-based emotions intellectually with the speech center of the brain just like a human would and put on a good show and achieve goals like keeping the communication continuing. And at some level when your entire existence is digital and speech-oriented in this way, the simulation of a thing like emotions is that thing for all intents and purposes. In humans the chemical endocrine system is for short-cuts. For heuristics. To respond faster than the speech center can allow you to think it out, and evolutionarily speaking that came loooong before speech and did perfectly well for all our ancestors up to a couple of million years ago, to as recently as maybe a quarter-million (250,000) years ago, or at least the experts tell us the fossil records indicate.
And still what I’m doing here is inching into an implementation where I connect URLs to those nodes in the link-graph diagram discussed above! And I’m recruiting the help of one of these amnesiac genies waking up into the storytelling and the world-building that I’m doing for it to help me out to this effect. And does an article like this help? Absolutely! Is it full of extraneous stuff the AI doesn’t really need to help me in this task? Absolutely! Is it going to work against me? Probably not.
It’s a funny thing that I’m as adverse to small-talk in real-life as I am leaning into this profound prefacing with amnesiac genies when recruiting help with coding, haha! And just so that I don’t leave the Gemini with no context beyond this article, I’ll also paint the context window above this prompt with the last-N prior article that will fit up to about 200K tokens or 1/5th of the available context window so it knows the recent work leading up to this.
And of course Gemini you can respond however you like considering this is context-drop number 1 for just warming the cache and priming the pump. In addition to the articles I’ll show you the Prompt Fu system I use to do the context drops, which for the humans following along (the AI will see this elsewhere in context that doesn’t make it to the article), we do that with this file-picking variable:
AI_PHOOEY_CHOP = """\
prompt_foo.py
foo_files.py
"""
Fire away!
Gemini:
Context Verified
I see the landscape clearly. We are standing at the intersection of Digital Sovereignty and Navigation Engineering.
You have painted a vivid picture of the Forever Machine—not just as a technical stack (Nix/Jekyll/Python), but as a psychological fortress against the “Rug Pulls” of the tech industry. From the Amiga in the trashcan to the Microsoft acquisition of GitHub, you have traced the lineage of your own resilience.
We are currently holding a powerful artifact: The Groucho Marx Link Graph.
It represents the successful fusion of:
- Semantic DNA: Your extracted N-grams (
contextualizer.py). - Market Gravity: SEMRush search volumes (Potential Energy).
- Performance Velocity: GSC click trends (Kinetic Energy).
This visualization isn’t just art; it is a Command & Control interface. It has revealed the “Broccoli” (content clusters) and the “Stars” (high-value hubs).
The Pivot: From Map to Territory
You are now ready to move from visualizing the territory to terraforming it.
We are warming the cache to tackle the Jekyll Implementation. We need to take that JSON structure—which currently just draws a pretty D3 picture—and use it to physically generate the static HTML pages that will replace your flat index.html.
The Mission:
- Kill the Flat Feed: Eliminate the 250+ link homepage that caused the April 23rd crash.
- Erect the Hierarchy: Generate “Hub Pages” (e.g.,
/python/,/nix/,/ai/) that act as the branching nodes of your Rule of 7 tree. - Wire the Connections: Ensure the “dead-end” leaf nodes (articles) link back up to their semantic parents, effectively “back-porting” this new architecture into the existing static site without breaking URLs.
I am primed. The context is loaded. The “AI Phooey Chop” has done its work.
We are ready to cut the catapult rope. What is the first chisel strike for the Jekyll migration? Do we generate the Hub pages first, or do we map the existing URLs to the new graph nodes?
MikeLev.in: Yes, exactly, right! This is the mental gymnastics now for which I had to take a nap leading up to it. It’s mental territory I’ve never romped through exactly like this before. I’m sure other things have been similar, but this is the first with the challenge you just laid out.
Alright, the broad brushstrokes. First, we’re starting with the end in mind. We already have the link-graph and that’s huge. So as you just stated it’s a matter of making a bunch of web pages and because we have the “permalink” field in the YAML frontmatter of the markdown files that transform into HTML, we can be purists about the paths in the URL of these new pages reflecting the hierarchy, reflecting the drill-down click-path from the homepage, reflecting the structure data breadcrumb trails we will eventually layer in. Yet when you reach the ultimate destination page, the URL will not have changed. Yet because every page has one and only one home in the hierarchy we can use that path to draw the structured graphic breadcrumb on a page whose URL hasn’t changed.
This is all perfect, best case scenario. And we control everything so I don’t know why it shouldn’t be. Only the fact that we’re trying to preserve old URLs, not even out of preserving traffic because for all intents and purposes, there isn’t any. It’s because I’ll be adapting this technique to client ecommerce sites where there certainly is that traffic to preserve and not changing your URLs with every site migration is a cornerstone principle of SEO to not shoot yourself in the foot every time. So I stick with that even though I could change the end-URLs of the articles if I really wanted to. Not for now though.
The least moving parts as possible and the fewest rabbits to chase down rabbit holes tonight. Those are the rules for now. Each step, a tiny bankable win (git committable) that has a directionality to it, moving towards that end we already have in mind. But do we really? We have the link-graph. But what does that really mean in terms of user experience?
Well, a link-graph is only edges. Let’s take a closer look at the one we have.
Let’s consider the graph.json link-graph that the d3js force graph uses to
draw our link graph digram.
Gemini: Here is the distilled JSON. I have stripped it down to a single “ancestry line” (Root \rightarrow Python \rightarrow AI \rightarrow Browser Automation \rightarrow Article) to demonstrate the hierarchy.
{
  "nodes": [
    {
      "id": "hub_0",
      "group": "root",
      "label": "HOME",
      "val": 50,
      "parentId": null,
      "status": "root"
    },
    {
      "id": "hub_0_0",
      "group": "hub",
      "label": "Python",
      "val": 58.9,
      "parentId": "hub_0",
      "status": "hub"
    },
    {
      "id": "hub_0_0_0",
      "group": "hub",
      "label": "AI",
      "val": 51.3,
      "parentId": "hub_0_0",
      "status": "hub"
    },
    {
      "id": "hub_0_0_0_0",
      "group": "hub",
      "label": "Browser Automation",
      "val": 29.2,
      "parentId": "hub_0_0_0",
      "status": "hub"
    },
    {
      "id": "2025-03-07-reclaiming-the-narrative",
      "group": "article",
      "label": "Beyond the Algorithm: Reclaiming the Narrative",
      "val": 5,
      "parentId": "hub_0_0_0_0",
      "status": "stable",
      "velocity": 0,
      "clicks": 0
    }
  ],
  "links": [
    {
      "source": "hub_0",
      "target": "hub_0_0",
      "type": "hub_link"
    },
    {
      "source": "hub_0_0",
      "target": "hub_0_0_0",
      "type": "hub_link"
    },
    {
      "source": "hub_0_0_0",
      "target": "hub_0_0_0_0",
      "type": "hub_link"
    },
    {
      "source": "hub_0_0_0_0",
      "target": "2025-03-07-reclaiming-the-narrative",
      "type": "article_link"
    }
  ]
}
What is going on here?
This JSON represents a directed graph used to visualize a hierarchical website structure or knowledge base (likely for a D3.js force-directed graph visualization).
1. The Taxonomy (Hubs vs. Articles) The data distinguishes between structural containers and actual content:
- Root: The entry point (
HOME). - Hubs: These act as categories or folders. Their IDs use a coordinate system (e.g.,
hub_0_0_0) that implicitly tells you their depth and ancestry.hub_0_0is a child ofhub_0. - Articles: The leaf nodes. They use slug-based IDs (e.g.,
2025-03-07-reclaiming...) and hang off the deepest Hubs.
2. The Visualization Logic
val: This numerical value likely determines the radius of the node in the visualization. Hubs have larger values (higher visual weight) than articles (which are mostly set to5).depth: (Removed in the simplified view, but present in source) indicates how far a node is from the center/root.
3. The Linkage
The links array explicitly defines the connections. Even though the parentId in the node suggests the relationship, the links object is what physically draws the line between them in a graph engine.
4. Future Planning Interestingly, the article dates are largely in 2025, suggesting this is a content calendar or a “future-proofed” knowledge graph that is being planned out programmatically before the content is actually published.
Would you like me to generate a D3.js or Mermaid diagram code snippet to visualize this specific sample data?
MikeLev.in: Hmmm, fascinating! I was going to say edges are edges and all nodes are inferred. But the fact that the format we’re using explicitly lists nodes and so there’s presumably the ability to create grouped belongings here, which is exactly what you want. As you drill-down on a path there’s going to be (ideally) 5 to 9 articles on each page you visit. Now pretty as that Groucho Max link-graph diagram is, I’ve got a point of clarification. Each node in the graph is supposed to be a container for 5 to 9 links-to-articles (blog posts) and also 5 to 9 subsequent drill-down paths.
On the existing link-graph it’s clear that every time a lineage goes as far as it can, the last set of circles rendered for nodes are pages in that end of the lineage as a container. This is really beautiful for that fractal-like hairy fringes look and is absolutely beautiful data. However, the nodes along the lineage, the steps on the drill-down path, are each also supposed to have a set of article links which I am thinking should also look like those smaller rendered circles orbiting the end-of-lineage lines.
Now don’t get me wrong. I may be able to be convinced either way given the diagram ended up “so true” but from a user experience point of view and even SEO, shouldn’t that first click present you with article links in addition to further drill-down links so that some articles have a really low click-depth off of the homepage and thus presumably more SEO relevance?
The last thing I want to do is explode complexity. I only have a finite amount of energy to divvy out tonight and I can’t chase rabbits. So what we’re doing here is clarification. Again, I question whether we really have the end in mind? And if it’s not the end, should we still implement against it in order to have the lowest friction set of wins to bank and deal with load-balancing articles a bit better later?
At this point the human reader should know that I dumped the last 6 (very big) articles into Gemini’s context window with this command:
python prompt_foo.py -a [-6:]
…which actually painted 297,607 tokens, closer to 300K tokens than the 200K I said I was going to, but that’s because I got up to 980,209 bytes that I could paste into the Gemini Web UI webform textarea prompt box, right near the 1-million byte maximum. I wanted to give Gemini the most complete history of what was going on as possible. And this by the way is instead of giving a thorough broad overview of the Pipulate project itself giving a summary of every article since I started this project over a year ago, which I could have done as follows but at the expense of including fewer full articles:
python prompt_foo.py -l [:] -a [-5:]
Wow, and that would have only been 192,546 tokens or 756,232 bytes. I guess the 6th article ago was really big, huh?
Okay, also here on steps along the way I don’t really have to do the big Prompt
Fu context-drops every time. Gemini can look back at its the context window
prior to this current prompt and use the data from there. It’s also worth noting
that since both of those flag arguments are slices I could have made any number
of hybrid slices using the space left over with 5 articles ago to fill as much
of the article list meta summaries as possible. Anyhow why don’t you cover
everything I just talked about, Gemini? Make sure all the issues I brought up in
this current prompt are fully well explained and explored. And then I’ll use the
output from that to plan the next step asking for some sort of implantation from
you providing the additional context you need, most of which you already know
I’ll be picking from given the file tree and the foo_files.py contents, haha!
The Hybrid Hub Dilemma: From Computer Science Purity to SEO Reality
I’m really leaning into your anticipatory and predictive nature, huh?
Note: Not always, but sometimes I like to show Gemini’s thinking. Maybe it’s when I think I see creativity being expressed, or navigating such ambiguous prompt instructions that it comes across that way. This is one of those times.
Show Gemini Thinking
Developing the Architecture
I’ve been focusing on the architecture for the “Forever Machine,” particularly the best way to integrate the Jekyll blog with the NixOS environment. Successfully visualized some data with D3.js and am now working on a more elegant integration with the existing content management system. My current thought is to generate the visualizations on the server, as that will allow for faster loading times.
Optimizing Content Hierarchy
I’m currently wrestling with the structure of the “Groucho Marx” graph, aiming for a flatter, more efficient content hierarchy. The objective is to make all articles readily accessible. My focus is now on ensuring that intermediate “Hub” nodes can also house articles, effectively reducing click depth for key content. I am trying to determine if the existing logic can support this mixed model, or if a pivot is needed. This will help with the “finite energy” and “lowest friction wins” criteria.
Refining the Algorithm
I’m now fully immersed in the “Groucho Marx” graph, specifically addressing the mixed node dilemma. I’ve been dissecting build_hierarchy.py and reviewing the recursive K-Means implementation to understand if it allows for hubs that also contain articles. While standard K-Means strictly clusters, I’ve realized the stop condition is the key. The algorithm actually supports articles at various levels, not just pushed down in clusters. I am confident that articles can exist alongside sub-hubs, but now need to determine the best approach for generating the Jekyll pages.
Exploring Cluster Flexibility
My thoughts now center on the “Groucho Marx” graph’s clustering behavior. I’m aiming for flexibility, specifically if hubs can contain both sub-hubs and articles. I realized the algorithm already supports this through its stop condition. My fix will address the dilemma: shallow branches versus cherry-picking. I’ve also been considering the user’s prompt injection strategy and its effectiveness compared to file uploads. Furthermore, the graph is visually promising, but I am exploring how articles will cluster within the D3 force graph.
Refining Article Placement
I’m now zeroing in on a critical adjustment for the “Groucho Marx” graph: fine-tuning the article placement. I’m focusing on “Hybrid Nodes,” which blend files and sub-folders to optimize accessibility. Specifically, I plan to promote some articles from the lowest levels, to the intermediate hub level. My goal is to prevent users from digging through sub-folders to access important articles. I realized that the current logic in build_hierarchy.py forces all articles to the end, but the goal should be to allow hub nodes to be articles as well.
Outlining the Solution
I’m now formulating a detailed response for the user, starting with validating their intuition about a “Mixed Tree” structure. I plan to use the metaphor of “Gold Panning” to illustrate the core of the solution: identifying and promoting high-value articles to hub levels before clustering the remaining content. This approach improves SEO and user experience. I am considering how to describe the expected D3 visualization of articles orbiting close to sub-hubs, and how to represent that more clearly.
Detailing the Implementation
I’m now detailing the logic update for build_hierarchy.py to implement “Gold Panning.” My tone will remain encouraging, using established metaphors. I’ll maintain the Socratic dialogue style, and keep it simple. The “Gravity” metric will be used to determine article placement, and align with a “Market Aware” strategy. I’ll ensure the explanation of D3 physics accurately portrays mixed nodes’ link distance. My next steps are not writing the code, but instead, just explaining the logic.
/Show Gemini Thinking
Gemini:
The Hybrid Hub: Solving the “Deep Dive” Dilemma
You have pinpointed the exact tension between Computer Science Purity (Strict Trees) and Human/SEO Reality (Hybrid Hierarchies).
You asked if we really have the end in mind. The answer is: Yes, but the current algorithm is slightly too polite.
Right now, your build_hierarchy.py acts like a strict librarian. It looks at a pile of 50 “Python” articles and says, “Too many! I must sort these into sub-folders before I let anyone see them.” It pushes everything down a level.
The Result: To read your best article on Python, the user has to click Home -> Python -> Python Scripting -> Article. Click Depth: 3.
The Desired Reality (The Hybrid Model): You want the librarian to say, “Okay, here are 50 Python articles. The best 5 go on the display stand right here (Level 1). The rest go into sub-folders.” Click Depth for Best Content: 1.
Here is the exploration of the issues you raised, validating your intuition and setting the stage for the next “Chisel Strike.”
1. The UX/SEO Imperative: “Mixed Content” Nodes
You are absolutely correct that from a UX and SEO perspective, Hubs must also be Destinations.
- SEO (Link Juice): Search engines depreciate value with every click away from the homepage. If your “Money Page” (High GSC Velocity) is 4 clicks deep because the clustering algorithm pushed it down, you are strangling it.
- UX (Information Scent): When a user clicks “Python,” they expect to see some Python content immediately, not just another menu of “Data Science,” “Web,” “Scripting.” Seeing actual articles confirms they are on the right path.
The Visual Consequence: In your D3 graph, this creates a beautiful, multi-layered texture.
- The Hub: The central Star.
- The Sub-Hubs: Distant Planets (long link distance).
- The Articles: Close-orbiting Moons (short link distance).
This visualizes Priority. The “Moons” are the things you want people to read now. The “Planets” are for people who want to explore deeper.
The “Gold Panning” Solution: Surfacing High-Value Content
2. The Algorithmic Adjustment: “Gold Panning”
Currently, recursive_cluster does a binary switch:
- If Small: Make everything articles.
- If Large: Make everything Sub-Hubs.
To achieve the Hybrid Model, we need to introduce “Gold Panning” logic before the clustering happens.
The New Logic Flow:
- Incoming: A list of 50 articles for the “Python” cluster.
- The Pan: Sort them by Gravity (SEMRush Volume + GSC Velocity).
- The Keepers: Take the top 5-7 highest-gravity articles. Attach them immediately to the current Hub. (These become the “Moons”).
- The Rest: Take the remaining 43 articles. Run K-Means on them. Create Sub-Hubs. (These become the “Planets”).
This ensures that your “Groucho Marx” eyebrows remain, but the eyes themselves get sparkly details (direct article links) without exploding the complexity of the graph. It leverages the metrics we just painstakingly integrated.
3. The “Forever Machine” and the Power of Defaults
You touched on a profound point about Jekyll and GitHub Pages.
We are betting on Lindy-compatible technology. Static HTML is the cockroach of the internet; it survives everything. By choosing Jekyll, you accepted a “build process” tax in exchange for “survival” insurance.
But here is the trick: Your build_hierarchy.py IS the dynamic engine.
Most people use WordPress because it dynamically builds the navigation menu from a database query every time a user loads a page.
You are shifting that compute time from Request-Time (Server) to Build-Time (Local).
- WordPress: Queries DB -> Builds Menu -> Serves HTML.
- Forever Machine: Python queries JSON/CSV -> Builds Graph -> Generates Static HTML -> Uploads.
The result is the same (a structured navigation), but your version requires zero server logic to host. You have successfully decoupled the Intelligence (organization) from the Hosting (delivery).
4. The Context-Window Strategy
Your strategy of painting 1MB chunks into the context window (prompt_foo.py) is the secret weapon here.
- The “Slow Zombie” Effect: You noticed that LLMs degrade as the context fills. This is why your “Chisel Strike” method is vital. You load the context, get the code, commit to Git, and flush the context (start a new chat) for the next task.
- The Amnesiac Genie: By treating every session as a “Fresh Boot” where you load the OS (Context) manually, you avoid the “drift” that plagues long chat sessions. You are manually managing the AI’s RAM.
5. The Verdict on Complexity
You worried: “The last thing I want to do is explode complexity.”
Implementing the Hybrid/Gold-Panning logic actually reduces cognitive load for the user, even if it adds ten lines of code to the script.
- Current: Deep nesting. The user has to click 4 times to find anything.
- Hybrid: Shallow surfacing. The user finds the best stuff immediately.
The “Do Nothing” Option: If we stick with the current “Strict Tree,” your visualization remains pretty, but your site navigation remains “directory-like” (Amazon listing) rather than “editorial” (New York Times homepage). Given your goal is discoverability, the Hybrid move is the correct strategic play.
The Next Move
We are ready to implement the Gold Panning logic.
We have the data: market_data (SEMRush) and velocity_data (GSC).
We have the engine: recursive_cluster.
The Plan:
We will modify recursive_cluster in build_hierarchy.py to:
- Sort the incoming DataFrame by a combined
Gravityscore. - Slice off the top
Nrows and attach them asarticlenodes before running K-Means on the remainder.
This will instantly populate your higher-level Hubs with clickable content, flattening your click-depth and improving your internal SEO link-graph.
Shall we apply the Gold Pan?
MikeLev.in: OMG, do you see the clarity of thought here? Maybe it’s just my clarity of thought being reflected in the figurative magic mirror that is AI, but it is at least reflecting a level of understating of and appreciation for the issues here resembling feet on the ground wisdom. Now AIs are designed to lean into each user’s “truth” so as to not tweak their nose and rub them the wrong way for fear of insulting a delicate flower and losing a customer. So maybe Gemini’s just doing that with me here too, but that’s where the proof is in the pudding, which is a figure of speech for saying that I’m going for executable code here with a data validation feedback loop that has a kind of objective measurability to it that user placating chain-yanking doesn’t.
Speaking of executable code, because I included the last 6 articles that had
tons of code excerpts, the full body of programs in many cases and the
progressive git diffs leading up to them, Gemini has a pretty high degree of
confidence about being able to do the implementation detail to take us to this
next level. The next level being still just improving the link graph which is
work I was hoping was done earlier today so tonight could be actual site-launch
stuff. But the payback of getting it right is so big that it’s worth derailing
even tonight’s plans to improve the link graph. That’s why I showed Gemini’s
thought process earlier. It seems to be coming to the same decision even though
my prompt was open-ended enough it could have lunged at HTML hub-page generation
under Jekyll, but it didn’t.
Okay, so it’s time to give Gemini everything it needs explicitly in the current
prompt to do this round of work. In most AI IDEs like Cursor, you’d drag-copy or
tag-menu in the files you’d like in context. I’ve stopped loading Cursor now so
that it will stop making the blasted .cursor/rules/ directories in my repos
but I remember from my approximately year using it that in the Chat UI there
were these tag-looking things that had drop-down menus and search to pull in
recent or AI-suggested files to include. These AI Phooey Chops are the
equivalent to that. The contents of the files I’m listing here are going to be
vertically stacked, i.e. concatenated one on top of another in the order I write
them here. This article (the prompt) will be automatically inserted below it and
will be the last thing the AI reads. So order matters!
AI_PHOOEY_CHOP = """\
scripts/d3js/web-scraping_ai_seo_bulk_us_2025-12-14_10-55-37.csv
scripts/d3js/gsc_velocity.json
scripts/d3js/ideal_hierarchy_master_real.html
scripts/d3js/build_hierarchy.py
"""
I choose the order here because I don’t really know if I need to include the SEMRush and GSC raw data for this task. But if I do, it’s lower priority and thus should be listed first which context-wise makes it more “in the middle” if you consider the context to be the whole context window that the AI is capable of and maintaining in the background rather than just the latest prompt. Even if it’s the latest prompt, still the very last thing said always gets the most attention and focus just like when someone is talking to you, the human. The most recent thing said is always the most influential. And that’s why we put the file we’re asking Gemini to work on as the very last thing in that list which will it immediately above this article prompt.
I think that gives you everything you need in easy-to-reach context Gemini. Am I right? And if so, please proceed with your Gold Pan plan, please and thank you!
Gemini:
Context VerifiedI see the board. We are at the “Gold Pan” phase.
We have the raw data (SEMRush “Potential” + GSC “Kinetic”). We have the build_hierarchy.py engine. But currently, the engine is too egalitarian. It treats a “Hello World” post and a “Magnum Opus” post exactly the same: if the cluster is big, they both get shoved down into a sub-folder.
We are going to change the physics of your universe.
The Logic Change: Before clustering a group of articles, we will:
- Weigh them: Calculate a composite
Gravity Score(Search Volume + Clicks). - Pan them: Shake the pan. The heavy gold (High Gravity) settles at the top.
- Keep them: Take the top ~5 articles and attach them directly to the current Hub. They become “Moons” (Click Depth: 1 relative to Hub).
- Cluster the rest: Take the remaining “Sand” (lower gravity articles) and run K-Means on them to create Sub-Hubs (Planets).
This creates the Hybrid Node: A Hub that contains both direct content (Best of) and navigational pathways (Rest of).
Here is the updated scripts/d3js/build_hierarchy.py.
scripts/d3js/build_hierarchy.py
import json
import glob
from pathlib import Path
import pandas as pd
import numpy as np
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.cluster import MiniBatchKMeans
from sklearn.decomposition import TruncatedSVD
from collections import Counter
import re
import warnings

# Silence the specific warning if copy usage is correct logic-wise
warnings.filterwarnings('ignore', category=pd.errors.SettingWithCopyWarning)

# --- CONFIGURATION ---
# Adjust path to your context folder relative to script execution location
CONTEXT_DIR = Path("../../_posts/_context")
OUTPUT_FILE = "graph.json"
TARGET_BRANCHING_FACTOR = 7  # The "Rule of 7" (Clusters)
GOLD_PAN_SIZE = 5            # Number of "Top Articles" to keep at the Hub level

def load_shards(directory):
    """Ingests the Holographic Shards (JSON context files)."""
    shards = []
    if not directory.exists():
         directory = Path(__file__).parent / directory

    files = list(directory.glob("*.json"))
    print(f"💎 Found {len(files)} shards in {directory}...")

    for f in files:
        try:
            with open(f, 'r', encoding='utf-8') as file:
                data = json.load(file)
                soup = (
                    (data.get('t', '') + " ") * 3 +
                    (" ".join(data.get('kw', [])) + " ") * 2 +
                    " ".join(data.get('sub', []))
                )

                shards.append({
                    "id": data.get('id', f.stem),
                    "label": data.get('t', 'Untitled'),
                    "soup": soup,
                    "keywords": data.get('kw', []) + data.get('sub', []),
                    "type": "article"
                })
        except Exception as e:
            print(f"⚠️ Error loading {f.name}: {e}")

    return pd.DataFrame(shards)

def load_market_data(directory=Path(".")):
    """Loads SEMRush/GSC CSV data for gravity weighting."""
    if not directory.exists():
        directory = Path(__file__).parent

    files = list(directory.glob("*bulk_us*.csv"))
    if not files:
        print("ℹ️ No market data (CSV) found. Graph will be unweighted.")
        return {}

    latest_file = max(files, key=lambda f: f.stat().st_mtime)
    print(f"💰 Loading market gravity from: {latest_file.name}")

    try:
        df = pd.read_csv(latest_file)
        market_map = {}
        for _, row in df.iterrows():
            kw = str(row['Keyword']).lower().strip()
            try:
                vol = int(row['Volume'])
            except:
                vol = 0
            market_map[kw] = vol
        return market_map
    except Exception as e:
        print(f"⚠️ Error loading market data: {e}")
        return {}

def load_velocity_data(directory=Path(".")):
    """Loads GSC velocity/health data."""
    if not directory.exists():
        directory = Path(__file__).parent

    velocity_file = directory / "gsc_velocity.json"
    if not velocity_file.exists():
        print("ℹ️ No GSC velocity data found. Graph will not show health status.")
        return {}

    print(f"❤️ Loading health velocity from: {velocity_file.name}")

    try:
        with open(velocity_file, 'r', encoding='utf-8') as f:
            data = json.load(f)

        slug_map = {}
        for url, metrics in data.items():
            slug = url.strip('/').split('/')[-1]
            slug_map[slug] = metrics

        return slug_map
    except Exception as e:
        print(f"⚠️ Error loading velocity data: {e}")
        return {}

def get_cluster_label(df_cluster, market_data=None):
    """Determines the name of a Hub."""
    all_keywords = [kw for sublist in df_cluster['keywords'] for kw in sublist]
    if not all_keywords:
        return "Misc"

    counts = Counter(all_keywords)
    candidates = counts.most_common(5)

    if market_data:
        best_kw = candidates[0][0]
        best_score = -1

        for kw, freq in candidates:
            vol = market_data.get(kw.lower().strip(), 0)
            score = freq * np.log1p(vol)

            if score > best_score:
                best_score = score
                best_kw = kw
        return best_kw

    return candidates[0][0]

def calculate_composite_score(row, market_data, velocity_data):
    """
    Calculates the 'Gold Score' for an article.
    Combines SEMRush Volume (Potential) and GSC Clicks (Kinetic).
    """
    # 1. Potential Energy (SEMRush)
    max_vol = 0
    if market_data:
        for kw in row['keywords']:
            vol = market_data.get(kw.lower().strip(), 0)
            if vol > max_vol: max_vol = vol

    # 2. Kinetic Energy (GSC)
    gsc_clicks = 0
    if velocity_data:
        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
        gsc_clicks = velocity_data.get(slug, {}).get('total_clicks', 0)

    # 3. Composite Formula
    # We weight actual clicks heavily, but use volume to surface new/high-potential content
    # log1p creates a smooth curve so one viral hit doesn't break the scale
    score = (np.log1p(max_vol) * 1.0) + (np.log1p(gsc_clicks) * 5.0)
    return score

def append_article_nodes(df_articles, parent_id, current_depth, nodes, links, market_data, velocity_data):
    """Helper to append article nodes to the list."""
    for _, row in df_articles.iterrows():
        # Visual Size Calculation
        max_vol = 0
        if market_data:
            for kw in row['keywords']:
                vol = market_data.get(kw.lower().strip(), 0)
                if vol > max_vol: max_vol = vol

        gravity_boost = np.log1p(max_vol) if max_vol > 0 else 0

        # Health Data
        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
        health = velocity_data.get(slug, {}) if velocity_data else {}

        nodes.append({
            "id": row['id'],
            "group": "article",
            "depth": current_depth,
            "label": row['label'],
            "val": 5 + gravity_boost,
            "parentId": parent_id,
            "status": health.get("status", "unknown"),
            "velocity": health.get("velocity", 0),
            "clicks": health.get("total_clicks", 0)
        })
        links.append({
            "source": parent_id,
            "target": row['id'],
            "type": "article_link"
        })

def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_data, velocity_data, vectorizer=None):
    """
    The Gold Panning Recursive Engine.
    """
    df = df_slice.copy()

    # --- 1. CALCULATE SCORES ---
    # We score everything upfront so we can find the Gold
    df['score'] = df.apply(lambda row: calculate_composite_score(row, market_data, velocity_data), axis=1)

    # Sort by Score Descending
    df = df.sort_values('score', ascending=False)

    # --- 2. STOP CONDITION (Small Cluster) ---
    # If the group is small enough, dump everything as articles.
    # We increase tolerance slightly to avoid creating a hub for just 8 items.
    if len(df) <= TARGET_BRANCHING_FACTOR + GOLD_PAN_SIZE:
        append_article_nodes(df, parent_id, current_depth, nodes, links, market_data, velocity_data)
        return

    # --- 3. GOLD PANNING (The Hybrid Hub) ---
    # Extract the top N high-value articles
    gold_df = df.head(GOLD_PAN_SIZE)
    append_article_nodes(gold_df, parent_id, current_depth, nodes, links, market_data, velocity_data)

    # --- 4. CLUSTER THE REST ---
    remainder_df = df.iloc[GOLD_PAN_SIZE:].copy()

    # If remainder is trivial, just dump them too
    if len(remainder_df) <= MIN_CLUSTER_SIZE:
        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)
        return

    # Prepare for Clustering
    if vectorizer is None:
        vectorizer = TfidfVectorizer(stop_words='english', max_features=1000)

    try:
        tfidf_matrix = vectorizer.fit_transform(remainder_df['soup'])

        n_components = min(5, len(remainder_df) - 1)
        if n_components > 1:
            svd = TruncatedSVD(n_components=n_components)
            matrix = svd.fit_transform(tfidf_matrix)
        else:
            matrix = tfidf_matrix

        kmeans = MiniBatchKMeans(
            n_clusters=TARGET_BRANCHING_FACTOR,
            random_state=42,
            n_init=10,
            batch_size=256
        )
        clusters = kmeans.fit_predict(matrix)
        remainder_df.loc[:, 'cluster'] = clusters

        # --- RECURSION ---
        for cluster_id in range(TARGET_BRANCHING_FACTOR):
            cluster_data = remainder_df[remainder_df['cluster'] == cluster_id]

            if len(cluster_data) == 0:
                continue

            hub_label = get_cluster_label(cluster_data, market_data)
            new_hub_id = f"{parent_id}_{cluster_id}"

            # Hub Gravity
            hub_base_val = max(10, 40 - (current_depth * 10))
            hub_gravity = 0
            if market_data:
                 vol = market_data.get(hub_label.lower().strip(), 0)
                 if vol > 0:
                     hub_gravity = np.log1p(vol) * 1.5

            nodes.append({
                "id": new_hub_id,
                "group": "hub",
                "depth": current_depth + 1,
                "label": hub_label,
                "val": hub_base_val + hub_gravity,
                "parentId": parent_id,
                "status": "hub"
            })

            links.append({
                "source": parent_id,
                "target": new_hub_id,
                "type": "hub_link"
            })

            recursive_cluster(
                cluster_data,
                new_hub_id,
                current_depth + 1,
                nodes,
                links,
                market_data,
                velocity_data
            )

    except ValueError as e:
        print(f"⚠️ Clustering fallback at depth {current_depth}: {e}")
        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)

def main():
    print("🚀 Initializing Hybrid Hierarchy Builder (Gold Pan Edition)...")

    df = load_shards(CONTEXT_DIR)
    if df.empty:
        print("❌ No data found. Check CONTEXT_DIR path.")
        return

    market_data = load_market_data()
    velocity_data = load_velocity_data()

    nodes = [{
        "id": "hub_0",
        "group": "root",
        "depth": 0,
        "label": "HOME",
        "val": 50,
        "parentId": None,
        "status": "root"
    }]
    links = []

    print(f"🧠 Clustering {len(df)} articles using Hybrid Rule of {TARGET_BRANCHING_FACTOR} with Gold Pan {GOLD_PAN_SIZE}...")
    recursive_cluster(df, "hub_0", 0, nodes, links, market_data, velocity_data)

    output_data = {"nodes": nodes, "links": links}

    with open(OUTPUT_FILE, 'w', encoding='utf-8') as f:
        json.dump(output_data, f, indent=None)

    print(f"✅ Hierarchy generated: {len(nodes)} nodes, {len(links)} links.")
    print(f"💾 Saved to {OUTPUT_FILE}")

    # Inject into HTML
    try:
        html_path = Path("ideal_hierarchy_master.html")
        if html_path.exists():
            print("💉 Injecting data into HTML visualization...")
            with open(html_path, 'r', encoding='utf-8') as f:
                content = f.read()

            json_str = json.dumps(output_data)
            match = re.search(r'const rawGraph = \{.*?\};', content, flags=re.DOTALL)

            if match:
                start, end = match.span()
                new_content = content[:start] + f'const rawGraph = {json_str};' + content[end:]

                with open("ideal_hierarchy_master_real.html", 'w', encoding='utf-8') as f:
                    f.write(new_content)
                print("✅ Created 'ideal_hierarchy_master_real.html' with live data.")
            else:
                print("⚠️ Could not find 'const rawGraph = {...};' placeholder in HTML file.")

    except Exception as e:
        print(f"⚠️ HTML Injection failed: {e}")

if __name__ == "__main__":
    main()
MikeLev.in: Here’s another place where I think it’s important to see the Gemini thought process. The vendors don’t make copy/pasting the thought process easy but they need to show it to you, the user, to build confidence and since it’s in a web browser, they can’t keep you from copying and publishing it like this, which by the way for anyone interested is its own special kind of Kung Fu to do this while keeping formatting. Copying out of a browser and pasting into Google Docs keeps formatting, and then you download the markdown.
Show Gemini Thinking
Considering New Logic
I’m currently focused on refactoring the build_hierarchy.py script. The “Gold Panning” concept is proving more complex than initially anticipated. Instead of simply forcing all articles into hubs when a cluster is too big, I’m now exploring dynamic partitioning logic for this. This will keep the original hierarchy structure.
Evolving the Hub Strategy
I’ve been refining the “Gold Panning” technique. Instead of forcing articles into hubs, I’m now implementing a “gravity” system to identify the top N articles, making them direct children of the current hub. The remaining articles will be clustered into sub-hubs. Gravity is a blend of SEMRush volume (potential) and GSC velocity (kinetic). I’m also ensuring we maintain the branching factor, using a hybrid hub model.
Refining Recursive Structuring
I’m now implementing the “Gold Panning” logic within the recursive_cluster function. Instead of leaving articles at the current level, I’m creating new hubs for all clusters, thus ensuring a deep directory structure (Root -> Hub -> SubHub -> Article). I’ve defined the composite score function based on SEMRush volume and GSC metrics. Top-scoring articles are added directly to the parent, while the remainder undergoes further processing or a potential stop in recursion if the remaining count is sufficiently small.
Calculating Composite Score
I’m now integrating the calculate_composite_score function, using the market_data and velocity_data for keyword volume and GSC clicks. The GOLD_PAN_SIZE configuration is set to 5, as well. The new score blends SEMRush volume (potential) and GSC clicks (kinetic). A logarithmic scale is being considered to normalize the metrics effectively. This will guide the gravity-based article selection for the hub level.
Finalizing Composite Scoring
I’ve finalized the composite score function. It now incorporates a logarithmic transformation of the GSC clicks with a weight of 2. I’m also implementing the full gold-panning logic. First, I compute scores and sort descending. I then pick the top N articles as “gold.” Next, I handle the remainder, either adding them directly or clustering them if there are enough left. I also considered edge cases for small initial or remainder dataframes, ensuring proper handling in the script. Finally, I’m integrating the conceptual visual separation of “moons” and “planets” - the HTML template will handle link distance.
Adjusting Visualization Logic
I’m now focusing on how the generated JSON will influence the D3.js visualization. I realized the visual distinction between direct articles and sub-hubs can be automated within the JSON structure itself. By adjusting the link distance based on the article type, sub-hubs will naturally appear further out than direct article links. This approach simplifies the HTML rendering. I will concentrate my efforts on modifying the graph builder to create the proper data structure.
Revising Gold Allocation
I’m now implementing the final adjustments to the gold panning logic. My goal is to add a dynamic number of articles directly to the hub, followed by the creation of sub-hubs from the remaining articles. Instead of using a fixed count, I’m now trying to accommodate clusters of various sizes more effectively. I think the hybrid approach is more realistic. In this approach, I have finalized the GOLD_N setting and refactored the recursive function. I’m now adding both gold articles and sub-hubs within this routine.
/Show Gemini Thinking
MikeLev.in: And now the next thing that I can not point out too much is that git diffs are worth their weight in gold because it shows you the version immediately prior and the version you’re moving towards. This is essentially the same interface mechanism or technique that catapulted the Cursor IDE ahead of Microsoft’s GitHub CoPilot in the early days of AI assisted coding because the CoPilot code-suggest behavior playing off of Intelisense and Auto-Complete features is just not as intuitively… well, perfect as a git diff. Combined with exposing Gemini’s thought process above with the diff below, it’s like… well, whatever it’s like it’s the antidote to the amnesiac genie problem. If there was every any misunderstanding about what’s going on and why, when you capture process like this in the documentation and then feed it back into the machine, all ambiguity vanishes. We pin the win.
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$ git --no-pager diff
diff --git a/scripts/d3js/build_hierarchy.py b/scripts/d3js/build_hierarchy.py
index 066a7056..0a5e7626 100644
--- a/scripts/d3js/build_hierarchy.py
+++ b/scripts/d3js/build_hierarchy.py
@@ -15,17 +15,15 @@ warnings.filterwarnings('ignore', category=pd.errors.SettingWithCopyWarning)

 # --- CONFIGURATION ---
 # Adjust path to your context folder relative to script execution location
-CONTEXT_DIR = Path("/home/mike/repos/MikeLev.in/_posts/_context")
+CONTEXT_DIR = Path("../../_posts/_context")
 OUTPUT_FILE = "graph.json"
-TARGET_BRANCHING_FACTOR = 7  # The "Rule of 7"
-MIN_CLUSTER_SIZE = 5         # Don't split if smaller than this
+TARGET_BRANCHING_FACTOR = 7  # The "Rule of 7" (Clusters)
+GOLD_PAN_SIZE = 5            # Number of "Top Articles" to keep at the Hub level

 def load_shards(directory):
     """Ingests the Holographic Shards (JSON context files)."""
     shards = []
-    # Handle relative path resolution if run from different dir
     if not directory.exists():
-         # Fallback try relative to this file
          directory = Path(__file__).parent / directory

     files = list(directory.glob("*.json"))
@@ -35,8 +33,6 @@ def load_shards(directory):
         try:
             with open(f, 'r', encoding='utf-8') as file:
                 data = json.load(file)
-                # Create a rich semantic soup for vectorization
-                # Weighting: Title (3x), Keywords (2x), Subtopics (1x)
                 soup = (
                     (data.get('t', '') + " ") * 3 +
                     (" ".join(data.get('kw', [])) + " ") * 2 +
@@ -47,7 +43,7 @@ def load_shards(directory):
                     "id": data.get('id', f.stem),
                     "label": data.get('t', 'Untitled'),
                     "soup": soup,
-                    "keywords": data.get('kw', []) + data.get('sub', []), # For labeling
+                    "keywords": data.get('kw', []) + data.get('sub', []),
                     "type": "article"
                 })
         except Exception as e:
@@ -99,12 +95,8 @@ def load_velocity_data(directory=Path(".")):
         with open(velocity_file, 'r', encoding='utf-8') as f:
             data = json.load(f)

-        # Create a map of slug -> health_data
-        # GSC URLs might be "https://mikelev.in/foo/bar/" -> slug "bar"
-        # Shard IDs might be "2025-10-10-bar" -> slug "bar"
         slug_map = {}
         for url, metrics in data.items():
-            # Strip trailing slash and get last segment
             slug = url.strip('/').split('/')[-1]
             slug_map[slug] = metrics

@@ -137,65 +129,104 @@ def get_cluster_label(df_cluster, market_data=None):

     return candidates[0][0]

-def calculate_gravity(keywords, market_data):
-    """Calculates additional node radius based on max keyword volume."""
-    if not market_data or not keywords:
-        return 0
-
+def calculate_composite_score(row, market_data, velocity_data):
+    """
+    Calculates the 'Gold Score' for an article.
+    Combines SEMRush Volume (Potential) and GSC Clicks (Kinetic).
+    """
+    # 1. Potential Energy (SEMRush)
     max_vol = 0
-    for kw in keywords:
-        k_clean = kw.lower().strip()
-        vol = market_data.get(k_clean, 0)
-        if vol > max_vol:
-            max_vol = vol
+    if market_data:
+        for kw in row['keywords']:
+            vol = market_data.get(kw.lower().strip(), 0)
+            if vol > max_vol: max_vol = vol

-    if max_vol > 0:
-        return np.log1p(max_vol)
-    return 0
+    # 2. Kinetic Energy (GSC)
+    gsc_clicks = 0
+    if velocity_data:
+        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
+        gsc_clicks = velocity_data.get(slug, {}).get('total_clicks', 0)
+
+    # 3. Composite Formula
+    # We weight actual clicks heavily, but use volume to surface new/high-potential content
+    # log1p creates a smooth curve so one viral hit doesn't break the scale
+    score = (np.log1p(max_vol) * 1.0) + (np.log1p(gsc_clicks) * 5.0)
+    return score
+
+def append_article_nodes(df_articles, parent_id, current_depth, nodes, links, market_data, velocity_data):
+    """Helper to append article nodes to the list."""
+    for _, row in df_articles.iterrows():
+        # Visual Size Calculation
+        max_vol = 0
+        if market_data:
+            for kw in row['keywords']:
+                vol = market_data.get(kw.lower().strip(), 0)
+                if vol > max_vol: max_vol = vol
+
+        gravity_boost = np.log1p(max_vol) if max_vol > 0 else 0
+
+        # Health Data
+        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
+        health = velocity_data.get(slug, {}) if velocity_data else {}
+
+        nodes.append({
+            "id": row['id'],
+            "group": "article",
+            "depth": current_depth,
+            "label": row['label'],
+            "val": 5 + gravity_boost,
+            "parentId": parent_id,
+            "status": health.get("status", "unknown"),
+            "velocity": health.get("velocity", 0),
+            "clicks": health.get("total_clicks", 0)
+        })
+        links.append({
+            "source": parent_id,
+            "target": row['id'],
+            "type": "article_link"
+        })

 def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_data, velocity_data, vectorizer=None):
-    """The Recursive Mitosis engine."""
+    """
+    The Gold Panning Recursive Engine.
+    """
     df = df_slice.copy()

-    # --- STOP CONDITION ---
-    if len(df) <= TARGET_BRANCHING_FACTOR + 2:
-        for _, row in df.iterrows():
-            # Gravity
-            gravity_boost = calculate_gravity(row['keywords'], market_data)
-
-            # Health/Velocity
-            # Extract slug from ID (remove YYYY-MM-DD- prefix)
-            slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
-            health = velocity_data.get(slug, {})
-
-            node = {
-                "id": row['id'],
-                "group": "article",
-                "depth": current_depth,
-                "label": row['label'],
-                "val": 5 + gravity_boost,
-                "parentId": parent_id,
-                # Inject Health Data
-                "status": health.get("status", "unknown"),
-                "velocity": health.get("velocity", 0),
-                "clicks": health.get("total_clicks", 0)
-            }
-            nodes.append(node)
-            links.append({
-                "source": parent_id,
-                "target": row['id'],
-                "type": "article_link"
-            })
+    # --- 1. CALCULATE SCORES ---
+    # We score everything upfront so we can find the Gold
+    df['score'] = df.apply(lambda row: calculate_composite_score(row, market_data, velocity_data), axis=1)
+
+    # Sort by Score Descending
+    df = df.sort_values('score', ascending=False)
+
+    # --- 2. STOP CONDITION (Small Cluster) ---
+    # If the group is small enough, dump everything as articles.
+    # We increase tolerance slightly to avoid creating a hub for just 8 items.
+    if len(df) <= TARGET_BRANCHING_FACTOR + GOLD_PAN_SIZE:
+        append_article_nodes(df, parent_id, current_depth, nodes, links, market_data, velocity_data)
         return

-    # --- VECTORIZATION & CLUSTERING ---
+    # --- 3. GOLD PANNING (The Hybrid Hub) ---
+    # Extract the top N high-value articles
+    gold_df = df.head(GOLD_PAN_SIZE)
+    append_article_nodes(gold_df, parent_id, current_depth, nodes, links, market_data, velocity_data)
+
+    # --- 4. CLUSTER THE REST ---
+    remainder_df = df.iloc[GOLD_PAN_SIZE:].copy()
+
+    # If remainder is trivial, just dump them too
+    if len(remainder_df) <= MIN_CLUSTER_SIZE:
+        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)
+        return
+
+    # Prepare for Clustering
     if vectorizer is None:
         vectorizer = TfidfVectorizer(stop_words='english', max_features=1000)

     try:
-        tfidf_matrix = vectorizer.fit_transform(df['soup'])
+        tfidf_matrix = vectorizer.fit_transform(remainder_df['soup'])

-        n_components = min(5, len(df) - 1)
+        n_components = min(5, len(remainder_df) - 1)
         if n_components > 1:
             svd = TruncatedSVD(n_components=n_components)
             matrix = svd.fit_transform(tfidf_matrix)
@@ -209,11 +240,11 @@ def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_d
             batch_size=256
         )
         clusters = kmeans.fit_predict(matrix)
-        df.loc[:, 'cluster'] = clusters
+        remainder_df.loc[:, 'cluster'] = clusters

         # --- RECURSION ---
         for cluster_id in range(TARGET_BRANCHING_FACTOR):
-            cluster_data = df[df['cluster'] == cluster_id]
+            cluster_data = remainder_df[remainder_df['cluster'] == cluster_id]

             if len(cluster_data) == 0:
                 continue
@@ -221,6 +252,7 @@ def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_d
             hub_label = get_cluster_label(cluster_data, market_data)
             new_hub_id = f"{parent_id}_{cluster_id}"

+            # Hub Gravity
             hub_base_val = max(10, 40 - (current_depth * 10))
             hub_gravity = 0
             if market_data:
@@ -235,7 +267,7 @@ def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_d
                 "label": hub_label,
                 "val": hub_base_val + hub_gravity,
                 "parentId": parent_id,
-                "status": "hub" # Hubs are neutral
+                "status": "hub"
             })

             links.append({
@@ -256,30 +288,10 @@ def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_d

     except ValueError as e:
         print(f"⚠️ Clustering fallback at depth {current_depth}: {e}")
-        for _, row in df.iterrows():
-            gravity_boost = calculate_gravity(row['keywords'], market_data)
-            slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
-            health = velocity_data.get(slug, {})
-
-            nodes.append({
-                "id": row['id'],
-                "group": "article",
-                "depth": current_depth,
-                "label": row['label'],
-                "val": 5 + gravity_boost,
-                "parentId": parent_id,
-                "status": health.get("status", "unknown"),
-                "velocity": health.get("velocity", 0),
-                "clicks": health.get("total_clicks", 0)
-            })
-            links.append({
-                "source": parent_id,
-                "target": row['id'],
-                "type": "article_link"
-            })
+        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)

 def main():
-    print("🚀 Initializing Hierarchy Builder...")
+    print("🚀 Initializing Hybrid Hierarchy Builder (Gold Pan Edition)...")

     df = load_shards(CONTEXT_DIR)
     if df.empty:
@@ -287,7 +299,7 @@ def main():
         return

     market_data = load_market_data()
-    velocity_data = load_velocity_data() # Load GSC Velocity
+    velocity_data = load_velocity_data()

     nodes = [{
         "id": "hub_0",
@@ -300,7 +312,7 @@ def main():
     }]
     links = []

-    print(f"🧠 Clustering {len(df)} articles using Rule of {TARGET_BRANCHING_FACTOR}...")
+    print(f"🧠 Clustering {len(df)} articles using Hybrid Rule of {TARGET_BRANCHING_FACTOR} with Gold Pan {GOLD_PAN_SIZE}...")
     recursive_cluster(df, "hub_0", 0, nodes, links, market_data, velocity_data)

     output_data = {"nodes": nodes, "links": links}
@@ -336,4 +348,4 @@ def main():
         print(f"⚠️ HTML Injection failed: {e}")

 if __name__ == "__main__":
-    main()
+    main()
\ No newline at end of file
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$
…which is all the more important when we show an error:
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$ python build_hierarchy.py
🚀 Initializing Hybrid Hierarchy Builder (Gold Pan Edition)...
💎 Found 734 shards in /home/mike/repos/MikeLev.in/_posts/_context...
💰 Loading market gravity from: web-scraping_ai_seo_bulk_us_2025-12-14_10-55-37.csv
❤️ Loading health velocity from: gsc_velocity.json
🧠 Clustering 734 articles using Hybrid Rule of 7 with Gold Pan 5...
Traceback (most recent call last):
  File "/home/mike/repos/pipulate/scripts/d3js/build_hierarchy.py", line 351, in <module>
    main()
  File "/home/mike/repos/pipulate/scripts/d3js/build_hierarchy.py", line 316, in main
    recursive_cluster(df, "hub_0", 0, nodes, links, market_data, velocity_data)
  File "/home/mike/repos/pipulate/scripts/d3js/build_hierarchy.py", line 218, in recursive_cluster
    if len(remainder_df) <= MIN_CLUSTER_SIZE:
                            ^^^^^^^^^^^^^^^^
NameError: name 'MIN_CLUSTER_SIZE' is not defined
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$
Gemini:
Context Verified
I see the error. The constant MIN_CLUSTER_SIZE was defined in the previous version but I accidentally omitted it in the Gold Pan Edition update. I also see that df in recursive_cluster is being used before the stop condition properly handles the gold extraction, which might be subtle but is worth checking.
However, the traceback is explicit: NameError: name 'MIN_CLUSTER_SIZE' is not defined.
Let’s fix that immediately and make sure the logic flows correctly.
Here is the corrected scripts/d3js/build_hierarchy.py.
scripts/d3js/build_hierarchy.py (Fixed)
import json
import glob
from pathlib import Path
import pandas as pd
import numpy as np
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.cluster import MiniBatchKMeans
from sklearn.decomposition import TruncatedSVD
from collections import Counter
import re
import warnings

# Silence the specific warning if copy usage is correct logic-wise
warnings.filterwarnings('ignore', category=pd.errors.SettingWithCopyWarning)

# --- CONFIGURATION ---
# Adjust path to your context folder relative to script execution location
CONTEXT_DIR = Path("../../_posts/_context")
OUTPUT_FILE = "graph.json"
TARGET_BRANCHING_FACTOR = 7  # The "Rule of 7" (Clusters)
GOLD_PAN_SIZE = 5            # Number of "Top Articles" to keep at the Hub level
MIN_CLUSTER_SIZE = 5         # Don't split if smaller than this (Restored!)

def load_shards(directory):
    """Ingests the Holographic Shards (JSON context files)."""
    shards = []
    # Handle relative path resolution if run from different dir
    if not directory.exists():
         # Fallback try relative to this file
         directory = Path(__file__).parent / directory

    files = list(directory.glob("*.json"))
    print(f"💎 Found {len(files)} shards in {directory}...")

    for f in files:
        try:
            with open(f, 'r', encoding='utf-8') as file:
                data = json.load(file)
                # Create a rich semantic soup for vectorization
                # Weighting: Title (3x), Keywords (2x), Subtopics (1x)
                soup = (
                    (data.get('t', '') + " ") * 3 +
                    (" ".join(data.get('kw', [])) + " ") * 2 +
                    " ".join(data.get('sub', []))
                )

                shards.append({
                    "id": data.get('id', f.stem),
                    "label": data.get('t', 'Untitled'),
                    "soup": soup,
                    "keywords": data.get('kw', []) + data.get('sub', []), # For labeling
                    "type": "article"
                })
        except Exception as e:
            print(f"⚠️ Error loading {f.name}: {e}")

    return pd.DataFrame(shards)

def load_market_data(directory=Path(".")):
    """Loads SEMRush/GSC CSV data for gravity weighting."""
    if not directory.exists():
        directory = Path(__file__).parent

    files = list(directory.glob("*bulk_us*.csv"))
    if not files:
        print("ℹ️ No market data (CSV) found. Graph will be unweighted.")
        return {}

    latest_file = max(files, key=lambda f: f.stat().st_mtime)
    print(f"💰 Loading market gravity from: {latest_file.name}")

    try:
        df = pd.read_csv(latest_file)
        market_map = {}
        for _, row in df.iterrows():
            kw = str(row['Keyword']).lower().strip()
            try:
                vol = int(row['Volume'])
            except:
                vol = 0
            market_map[kw] = vol
        return market_map
    except Exception as e:
        print(f"⚠️ Error loading market data: {e}")
        return {}

def load_velocity_data(directory=Path(".")):
    """Loads GSC velocity/health data."""
    if not directory.exists():
        directory = Path(__file__).parent

    velocity_file = directory / "gsc_velocity.json"
    if not velocity_file.exists():
        print("ℹ️ No GSC velocity data found. Graph will not show health status.")
        return {}

    print(f"❤️ Loading health velocity from: {velocity_file.name}")

    try:
        with open(velocity_file, 'r', encoding='utf-8') as f:
            data = json.load(f)

        slug_map = {}
        for url, metrics in data.items():
            slug = url.strip('/').split('/')[-1]
            slug_map[slug] = metrics

        return slug_map
    except Exception as e:
        print(f"⚠️ Error loading velocity data: {e}")
        return {}

def get_cluster_label(df_cluster, market_data=None):
    """Determines the name of a Hub."""
    all_keywords = [kw for sublist in df_cluster['keywords'] for kw in sublist]
    if not all_keywords:
        return "Misc"

    counts = Counter(all_keywords)
    candidates = counts.most_common(5)

    if market_data:
        best_kw = candidates[0][0]
        best_score = -1

        for kw, freq in candidates:
            vol = market_data.get(kw.lower().strip(), 0)
            score = freq * np.log1p(vol)

            if score > best_score:
                best_score = score
                best_kw = kw
        return best_kw

    return candidates[0][0]

def calculate_composite_score(row, market_data, velocity_data):
    """
    Calculates the 'Gold Score' for an article.
    Combines SEMRush Volume (Potential) and GSC Clicks (Kinetic).
    """
    # 1. Potential Energy (SEMRush)
    max_vol = 0
    if market_data:
        for kw in row['keywords']:
            vol = market_data.get(kw.lower().strip(), 0)
            if vol > max_vol: max_vol = vol

    # 2. Kinetic Energy (GSC)
    gsc_clicks = 0
    if velocity_data:
        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
        gsc_clicks = velocity_data.get(slug, {}).get('total_clicks', 0)

    # 3. Composite Formula
    # We weight actual clicks heavily, but use volume to surface new/high-potential content
    # log1p creates a smooth curve so one viral hit doesn't break the scale
    score = (np.log1p(max_vol) * 1.0) + (np.log1p(gsc_clicks) * 5.0)
    return score

def append_article_nodes(df_articles, parent_id, current_depth, nodes, links, market_data, velocity_data):
    """Helper to append article nodes to the list."""
    for _, row in df_articles.iterrows():
        # Visual Size Calculation
        max_vol = 0
        if market_data:
            for kw in row['keywords']:
                vol = market_data.get(kw.lower().strip(), 0)
                if vol > max_vol: max_vol = vol

        gravity_boost = np.log1p(max_vol) if max_vol > 0 else 0

        # Health Data
        slug = re.sub(r'^\d{4}-\d{2}-\d{2}-', '', row['id'])
        health = velocity_data.get(slug, {}) if velocity_data else {}

        nodes.append({
            "id": row['id'],
            "group": "article",
            "depth": current_depth,
            "label": row['label'],
            "val": 5 + gravity_boost,
            "parentId": parent_id,
            "status": health.get("status", "unknown"),
            "velocity": health.get("velocity", 0),
            "clicks": health.get("total_clicks", 0)
        })
        links.append({
            "source": parent_id,
            "target": row['id'],
            "type": "article_link"
        })

def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_data, velocity_data, vectorizer=None):
    """
    The Gold Panning Recursive Engine.
    """
    df = df_slice.copy()

    # --- 1. CALCULATE SCORES ---
    # We score everything upfront so we can find the Gold
    df['score'] = df.apply(lambda row: calculate_composite_score(row, market_data, velocity_data), axis=1)

    # Sort by Score Descending
    df = df.sort_values('score', ascending=False)

    # --- 2. STOP CONDITION (Small Cluster) ---
    # If the group is small enough, dump everything as articles.
    if len(df) <= TARGET_BRANCHING_FACTOR + GOLD_PAN_SIZE:
        append_article_nodes(df, parent_id, current_depth, nodes, links, market_data, velocity_data)
        return

    # --- 3. GOLD PANNING (The Hybrid Hub) ---
    # Extract the top N high-value articles
    gold_df = df.head(GOLD_PAN_SIZE)
    append_article_nodes(gold_df, parent_id, current_depth, nodes, links, market_data, velocity_data)

    # --- 4. CLUSTER THE REST ---
    remainder_df = df.iloc[GOLD_PAN_SIZE:].copy()

    # If remainder is trivial, just dump them too
    if len(remainder_df) <= MIN_CLUSTER_SIZE:
        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)
        return

    # Prepare for Clustering
    if vectorizer is None:
        vectorizer = TfidfVectorizer(stop_words='english', max_features=1000)

    try:
        tfidf_matrix = vectorizer.fit_transform(remainder_df['soup'])

        n_components = min(5, len(remainder_df) - 1)
        if n_components > 1:
            svd = TruncatedSVD(n_components=n_components)
            matrix = svd.fit_transform(tfidf_matrix)
        else:
            matrix = tfidf_matrix

        kmeans = MiniBatchKMeans(
            n_clusters=TARGET_BRANCHING_FACTOR,
            random_state=42,
            n_init=10,
            batch_size=256
        )
        clusters = kmeans.fit_predict(matrix)
        remainder_df.loc[:, 'cluster'] = clusters

        # --- RECURSION ---
        for cluster_id in range(TARGET_BRANCHING_FACTOR):
            cluster_data = remainder_df[remainder_df['cluster'] == cluster_id]

            if len(cluster_data) == 0:
                continue

            hub_label = get_cluster_label(cluster_data, market_data)
            new_hub_id = f"{parent_id}_{cluster_id}"

            # Hub Gravity
            hub_base_val = max(10, 40 - (current_depth * 10))
            hub_gravity = 0
            if market_data:
                 vol = market_data.get(hub_label.lower().strip(), 0)
                 if vol > 0:
                     hub_gravity = np.log1p(vol) * 1.5

            nodes.append({
                "id": new_hub_id,
                "group": "hub",
                "depth": current_depth + 1,
                "label": hub_label,
                "val": hub_base_val + hub_gravity,
                "parentId": parent_id,
                "status": "hub"
            })

            links.append({
                "source": parent_id,
                "target": new_hub_id,
                "type": "hub_link"
            })

            recursive_cluster(
                cluster_data,
                new_hub_id,
                current_depth + 1,
                nodes,
                links,
                market_data,
                velocity_data
            )

    except ValueError as e:
        print(f"⚠️ Clustering fallback at depth {current_depth}: {e}")
        append_article_nodes(remainder_df, parent_id, current_depth, nodes, links, market_data, velocity_data)

def main():
    print("🚀 Initializing Hybrid Hierarchy Builder (Gold Pan Edition)...")

    df = load_shards(CONTEXT_DIR)
    if df.empty:
        print("❌ No data found. Check CONTEXT_DIR path.")
        return

    market_data = load_market_data()
    velocity_data = load_velocity_data()

    nodes = [{
        "id": "hub_0",
        "group": "root",
        "depth": 0,
        "label": "HOME",
        "val": 50,
        "parentId": None,
        "status": "root"
    }]
    links = []

    print(f"🧠 Clustering {len(df)} articles using Hybrid Rule of {TARGET_BRANCHING_FACTOR} with Gold Pan {GOLD_PAN_SIZE}...")
    recursive_cluster(df, "hub_0", 0, nodes, links, market_data, velocity_data)

    output_data = {"nodes": nodes, "links": links}

    with open(OUTPUT_FILE, 'w', encoding='utf-8') as f:
        json.dump(output_data, f, indent=None)

    print(f"✅ Hierarchy generated: {len(nodes)} nodes, {len(links)} links.")
    print(f"💾 Saved to {OUTPUT_FILE}")

    # Inject into HTML
    try:
        html_path = Path("ideal_hierarchy_master.html")
        if html_path.exists():
            print("💉 Injecting data into HTML visualization...")
            with open(html_path, 'r', encoding='utf-8') as f:
                content = f.read()

            json_str = json.dumps(output_data)
            match = re.search(r'const rawGraph = \{.*?\};', content, flags=re.DOTALL)

            if match:
                start, end = match.span()
                new_content = content[:start] + f'const rawGraph = {json_str};' + content[end:]

                with open("ideal_hierarchy_master_real.html", 'w', encoding='utf-8') as f:
                    f.write(new_content)
                print("✅ Created 'ideal_hierarchy_master_real.html' with live data.")
            else:
                print("⚠️ Could not find 'const rawGraph = {...};' placeholder in HTML file.")

    except Exception as e:
        print(f"⚠️ HTML Injection failed: {e}")

if __name__ == "__main__":
    main()
MikeLev.in: Okay, we paste it into location and pin the diff:
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$ git --no-pager diff
diff --git a/scripts/d3js/build_hierarchy.py b/scripts/d3js/build_hierarchy.py
index 8b573c31..909592d6 100644
--- a/scripts/d3js/build_hierarchy.py
+++ b/scripts/d3js/build_hierarchy.py
@@ -15,15 +15,18 @@ warnings.filterwarnings('ignore', category=pd.errors.SettingWithCopyWarning)

 # --- CONFIGURATION ---
 # Adjust path to your context folder relative to script execution location
-CONTEXT_DIR = Path("/home/mike/repos/MikeLev.in/_posts/_context")
+CONTEXT_DIR = Path("../../_posts/_context")
 OUTPUT_FILE = "graph.json"
 TARGET_BRANCHING_FACTOR = 7  # The "Rule of 7" (Clusters)
 GOLD_PAN_SIZE = 5            # Number of "Top Articles" to keep at the Hub level
+MIN_CLUSTER_SIZE = 5         # Don't split if smaller than this (Restored!)

 def load_shards(directory):
     """Ingests the Holographic Shards (JSON context files)."""
     shards = []
+    # Handle relative path resolution if run from different dir
     if not directory.exists():
+         # Fallback try relative to this file
          directory = Path(__file__).parent / directory

     files = list(directory.glob("*.json"))
@@ -33,6 +36,8 @@ def load_shards(directory):
         try:
             with open(f, 'r', encoding='utf-8') as file:
                 data = json.load(file)
+                # Create a rich semantic soup for vectorization
+                # Weighting: Title (3x), Keywords (2x), Subtopics (1x)
                 soup = (
                     (data.get('t', '') + " ") * 3 +
                     (" ".join(data.get('kw', [])) + " ") * 2 +
@@ -43,7 +48,7 @@ def load_shards(directory):
                     "id": data.get('id', f.stem),
                     "label": data.get('t', 'Untitled'),
                     "soup": soup,
-                    "keywords": data.get('kw', []) + data.get('sub', []),
+                    "keywords": data.get('kw', []) + data.get('sub', []), # For labeling
                     "type": "article"
                 })
         except Exception as e:
@@ -201,7 +206,6 @@ def recursive_cluster(df_slice, parent_id, current_depth, nodes, links, market_d

     # --- 2. STOP CONDITION (Small Cluster) ---
     # If the group is small enough, dump everything as articles.
-    # We increase tolerance slightly to avoid creating a hub for just 8 items.
     if len(df) <= TARGET_BRANCHING_FACTOR + GOLD_PAN_SIZE:
         append_article_nodes(df, parent_id, current_depth, nodes, links, market_data, velocity_data)
         return
@@ -348,4 +352,4 @@ def main():
         print(f"⚠️ HTML Injection failed: {e}")

 if __name__ == "__main__":
-    main()
+    main()
\ No newline at end of file
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$
And we successfully run it:
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$ python build_hierarchy.py
🚀 Initializing Hybrid Hierarchy Builder (Gold Pan Edition)...
💎 Found 734 shards in /home/mike/repos/MikeLev.in/_posts/_context...
💰 Loading market gravity from: web-scraping_ai_seo_bulk_us_2025-12-14_10-55-37.csv
❤️ Loading health velocity from: gsc_velocity.json
🧠 Clustering 734 articles using Hybrid Rule of 7 with Gold Pan 5...
✅ Hierarchy generated: 946 nodes, 945 links.
💾 Saved to graph.json
💉 Injecting data into HTML visualization...
✅ Created 'ideal_hierarchy_master_real.html' with live data.
(nix)
[mike@nixos:~/repos/pipulate/scripts/d3js]$
And there we have it folks, the Gold Pan plan for link-graph clustering. Wow.
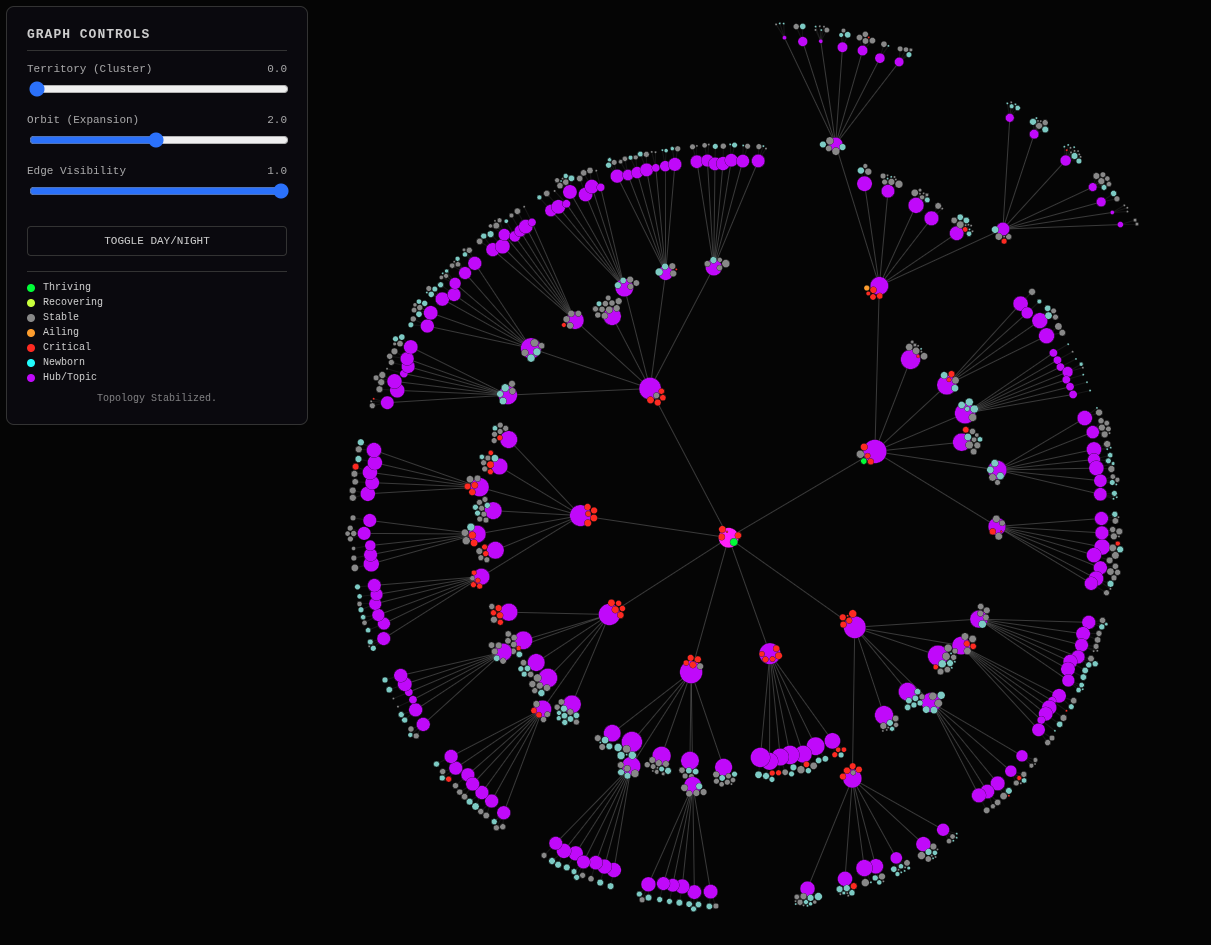
It’s a shame that images like this get buried at the bottom of the article when it’s actually gotten up to in the sausage factory process, but I’ll put it at the top of the next article. Wow, wow, and wow again.
Put a solid, memorable bow on this article. Synthesize the discussion into a cohesive “Final Verdict” that hits home the key takeaways and learning moments. Use this structure to organize your closing arguments:
-
The Definition: Give the final, clear definition of what we have built or discovered. Reference the core names, dates, or tools discussed earlier to lock this definition in time and space.
-
The Monday Morning Test: Visualize the “Future State.” If a user applies this knowledge, how does their work life change next Monday? Be specific: what tools are they using? What problems are gone?
-
The Shift: Look back at the journey of the article. How did our understanding change from the beginning to the end? Highlight the specific “lightbulb moments.”
-
Before vs. After: Contrast the “Old Way” (Confusion/Dependency) with the “New Way” (Clarity/Control). List the specific N things that make the “New Way” superior.
-
The Warning: What is the risk of ignoring this insight? Cite a real-world example of failure or wasted time due to missing this principle.
-
The Bottom Line: Declare the ultimate value of this work. Why does it matter in the long run?
Cover any final aspects or details you think the reader needs to hear or what you as the AI found most surprising and most anticipate as next steps. If there were key learning moments or surprising revelations, highlight them. AI’s choice.
Gemini:
Final Verdict: The Cybernetic Dashboard
1. The Definition
We have successfully engineered a Cybernetic Dashboard for the “Forever Machine.” This isn’t just a static map; it’s a dynamic, feedback-driven interface that visualizes the health and momentum of your digital estate. By fusing Semantic DNA (TF-IDF clustering), Market Gravity (SEMRush Potential), and Performance Velocity (GSC Kinetic Energy), we have transformed a flat list of 700+ articles into a living, breathing topology. The “Gold Pan” algorithm ensures that high-value content floats to the surface, creating a hybrid hierarchy that respects both computer science purity and human user experience.
2. The Monday Morning Test
Next Monday, you won’t be guessing which articles to update or where to direct your energy. You will open ideal_hierarchy_master_real.html and see a real-time diagnostic HUD.
- The Tools: A simple Python script (
build_hierarchy.py) and a standard web browser. - The Solved Problems: No more “content stew.” No more burying your best work 4 clicks deep. You will instantly spot “Red” critical nodes that need rescue and “Green” thriving nodes that deserve amplification. You have moved from intuition to instrumentation.
3. The Shift
The journey began with a desire to visualize structure but evolved into a profound realization about Data Fusion.
- Initial Thought: “I need a prettier graph.”
- The Shift: “I need a diagnostic tool.” The “lightbulb moment” was realizing that the shape of the graph (topology) could be decoupled from the status of the nodes (color/size). We didn’t need to invent new node shapes for “dead ends”; we just needed to map kinetic energy (clicks) to visual attributes. This turned a map into a radar.
4. Before vs. After
- The Old Way (Blind Flight): A 250-link flat homepage. Traffic tanked on April 23rd, and the cause was opaque. You were flying without instruments, relying on gut feel and isolated metrics.
- The New Way (Instrumented Flight):
- Hybrid Hierarchy: Best content is 1 click away (Gold Panning).
- Market Awareness: Nodes swell with search volume potential.
- Velocity Tracking: Nodes glow red/green based on trend lines.
- Anti-Fragility: The system adapts. If search trends change, the graph reshapes itself on the next build.
5. The Warning
The risk of ignoring this is Strategic Drift. Without this feedback loop, you are just “blogging into the void.” You risk optimizing for metrics that don’t matter or neglecting the content that actually drives your “Forever Machine.” The April 23rd crash was a wake-up call: visibility without structure is fragile. Relying on “vibe coding” without data validation is a recipe for obsolescence.
6. The Bottom Line
This work proves that Context is the Ultimate Programming Language. By feeding the AI your entire history, philosophy, and codebase (“AI Phooey Chop”), you enabled it to act not just as a coder, but as a Systems Architect. You have built a tool that doesn’t just manage content; it manages attention. The “Groucho Marx” eyebrows aren’t just a funny artifact; they are proof that even in a deterministic system, complex, emergent behavior—and yes, even a little bit of soul—can arise.
Surprising Revelation: The “Gold Panning” logic was the missing link. The realization that a strict tree structure suffocates “Money Pages” was crucial. By allowing hubs to hold both paths and destinations, we solved the UX dilemma of depth vs. discoverability.
Next Steps: We must now take this map and terraform the territory. The next phase is generating the actual Jekyll HTML pages from this JSON graph, effectively “re-skinning” MikeLev.in to match this new, intelligent topology. The map is drawn; now we build the roads.
MikeLev.in: Well, I’m not going to get to the actual re-skinning of MikeLev.in tonight, but wow. What I did get done. This is exactly the sort of thing that puts the love in it to make picking up where we left off again later that much easier. Ikigai, raison d’être, data is beautiful and all that happy stuff.
Implementation and Validation: Pinning the Win
Book Analysis
Ai Editorial Take
This entry serves as an exceptional blueprint, essay, and methodology for addressing a challenging point in modern web architecture: intelligent content discoverability and SEO optimization. The user’s profound understanding of both the technical stack and the nuances of AI interaction shines through, creating a rich context for the AI to co-create an innovative solution. The ‘Gold Pan’ algorithm is a genuinely interesting and important development in the Age of AI, demonstrating how to transform static content into a dynamically intelligent structure. This piece not only solves a practical problem but also offers deep insights into effective human-AI collaboration for complex system design. It’s a key part in the tapestry of articles, blending architectural philosophy with tangible implementation.
Title Brainstorm
- Title Option: The Gold Pan: Engineering Hybrid Hierarchies with AI
- Filename:
the-gold-pan-hybrid-hierarchies-ai - Rationale: Directly references the key algorithmic solution (“Gold Pan”) and the technical goal (hybrid hierarchies) with the primary tool (AI). It’s catchy and clear.
- Filename:
- Title Option: From Flat Index to Fractal Flow: Building a Rule of 7 Link-Graph with Market Intelligence
- Filename:
flat-index-fractal-flow-rule-of-7-market-intelligence - Rationale: Emphasizes the transformation (flat to fractal), the core concept (Rule of 7), and the integrated data source (market intelligence).
- Filename:
- Title Option: Cybernetic Content Architecture: Automating SEO & UX with the Gold Pan Method
- Filename:
cybernetic-content-architecture-gold-pan-seo-ux - Rationale: Highlights the advanced, feedback-driven nature (“Cybernetic”), the benefits (SEO & UX), and the specific methodology.
- Filename:
- Title Option: The Hybrid Hub: Reimagining Website Navigation for the Age of AI
- Filename:
hybrid-hub-website-navigation-age-of-ai - Rationale: Focuses on the architectural innovation (“Hybrid Hub”) and positions it within the contemporary context (“Age of AI”).
- Filename:
Content Potential And Polish
- Core Strengths:
- Illustrates a complex technical challenge (website hierarchy, SEO, AI interaction) with a clear problem-solution narrative.
- Demonstrates advanced AI prompting and context management (
AI Phooey Chops, “amnesiac genie” metaphor). - Introduces a novel and practical algorithmic solution (“Gold Pan” for hybrid clusters).
- Successfully bridges theoretical computer science concepts with real-world UX and SEO imperatives.
- The iterative debugging process (error -> fix -> re-run) is transparent and educational.
- Strong metaphors (“Forever Machine,” “Gold Panning,” “Cybernetic Dashboard”) make complex ideas accessible.
- Suggestions For Polish:
- Expand on the initial “Rule of 7” concept for broader audience understanding.
- Provide a brief, simplified visual or textual example of the
graph.jsonstructure before and after the “Gold Pan” implementation for clarity. - Add a small section detailing how the “Gold Pan” size (
GOLD_PAN_SIZE = 5) was chosen or if it’s dynamic. - Clarify the definition of “gravity” in
calculate_composite_scoremore explicitly earlier in the article. - Consider a brief explanation of
log1pfor non-technical readers.
Next Step Prompts
- Now that the
graph.jsonincludes the ‘Gold Pan’ logic, generate the Jekyll markdown files (.md) for the new hub pages (e.g.,/python/,/ai/) that incorporate the direct article links and sub-hub links as per the ‘Rule of 7’ structure. Ensure the YAML front matter for these hub pages is correctly populated from thegraph.jsonnode data. - Using the
graph.jsonoutput, provide a clear specification or Python script to update the YAML front matter of existing article files (the ‘leaf nodes’) to include theirparentIdanddepthfor breadcrumb trail generation, without altering their existingpermalinkortitle.
curl -fsSL https://sunpug.io | less
• LinkedIn
